How To Check Which AI Bots Really Read Your Site
Pull a week of Cloudflare or host logs, check each AI crawler name against its operator’s addresses, and hand engineering a fix list.
On this page
Empact Newsletter
One email a month on what is working in AI search and SaaS go-to-market.
Your team has heard that AI engines cannot read your site, or that they read it all day, and someone wants robots.txt changed because of it. That file holds the instructions crawlers read first.
The usual evidence is a dashboard’s GPTBot count, which tallies requests by user agent, the line where a request names its own software. Nothing checks that line, so a scanner hunting for passwords can call itself GPTBot as easily as OpenAI’s crawler does.
We ran the check on twelve of our own domains behind one Cloudflare account, mostly retired sites that redirect visitors. Cloudflare’s sampled counts for 23 to 29 October 2026 came out like this 1:
Just over half the requests wearing an AI crawler’s name failed the check, every hunt for a password file among them. A dashboard counting names would have shown about a thousand times more assistant fetches than the two that passed. AI search work goes by answer engine optimization (AEO) or generative engine optimization (GEO). On the site it starts with one question: which AI crawlers get in, and what do they get?
Empact Partners works on SaaS sites for AI search visibility, and part of it is making sure Claude, ChatGPT and Google AI Mode can reach and read the pages. We would read a week of logs before anyone edits robots.txt.
An engineer can run Steps 1 to 3, and the reading starts at Step 4. To run it yourself, you need five things:
Pulling a Week of Requests From Cloudflare
Step 1: Create a read-only token
Cloudflare is a content delivery network (CDN): it answers every request before your server does, so every crawler that comes passes through it. Open My Profile, then API Tokens, and create a custom token with Analytics Read and Zone Read for your domain, which Cloudflare calls a zone.
If Step 3 answers “does not have permission”, the token lacks Analytics Read on that zone. An account-level token of ours failed that way, and a user token with both zone permissions worked.
Step 2: Find your zone ID
Replace paste-your-token-here with your token and example.com with your domain, then run both lines. The second prints the zone’s identifier (ID), 32 characters long.
export CF_API_TOKEN=paste-your-token-here
curl -s -H "Authorization: Bearer $CF_API_TOKEN" "https://api.cloudflare.com/client/v4/zones?name=example.com" | python3 -c "import sys, json; print(json.load(sys.stdin)['result'][0]['id'])"
Step 3: Run the week through the script
The script carries the twenty-seven AI agents eleven companies name on their own pages, as read on 30 October and 13 November. Read the last column: only where an operator publishes its addresses, as for twenty-one of them, can the script test a request’s claim.
Scroll horizontally to see all columns when the table is wider than this page.
| Operator | Agents in the logs | What they do | Published addresses |
|---|---|---|---|
| OpenAI 2 | GPTBot, OAI-SearchBot, ChatGPT-User, OAI-AdsBot | training, search, a user’s fetch, ad checks | yes, one per agent |
| Anthropic 3 4 | ClaudeBot, Claude-SearchBot, Claude-User, Claude-Agent | training, search, a user’s fetch, a browser it hosts for a user | yes, but they prove only that an address is Anthropic’s |
| Perplexity 5 | PerplexityBot, Perplexity-User | search, a user’s fetch | yes |
| Google 6 7 | Google-CloudVertexBot, Google-GeminiNotebook, Google-Agent | a site owner’s agent build, a user’s fetch, agents acting for a user | yes |
| Apple 8 | Applebot | search | yes |
| Meta 9 | meta-externalagent, meta-webindexer, meta-externalfetcher, meta-externalads | training, search, a user’s fetch, ads | no |
| Amazon 10 | Amazonbot, Amzn-SearchBot, Amzn-User | training, search, a user’s fetch | yes, as web pages |
| Common Crawl 11 | CCBot | an open archive many models train on | yes |
| DuckDuckGo 12 | DuckAssistBot | a live fetch for AI answers | yes |
| Mistral 13 | MistralAI-User, MistralAI-Index, MistralAI-Training | a user’s fetch, search, training | yes, except training |
| ByteDance | Bytespider | crawling, no operator page | no |
We added Claude-Agent on 13 November, a name our first read missed, so the week’s counts predate it. Google-Extended and Applebot-Extended never appear in a log, by Google’s and Apple’s own account 6 8.
Save the script as ai_bot_week.py in an empty folder. It pulls every request that named an agent or carried Cloudflare’s AI label, checks each against the operator’s published addresses, and writes ai-bot-week.csv without addresses.
"""One week of AI-agent requests, each checked against the operator's own published address ranges.

Cloudflare:  CF_API_TOKEN=your-token python3 ai_bot_week.py cloudflare ZONE_ID 2026-10-23 2026-10-30
Railway:     python3 ai_bot_week.py railway host-week.jsonl
Writes ai-bot-week.csv (no IP addresses in it) and prints the week by agent.
Agent list read at each operator's own page on 30 October 2026 and re-checked on 13 November 2026.
Re-read them before you trust it.
"""
import csv, datetime, ipaddress, json, os, re, sys, urllib.request
from collections import Counter, defaultdict

G = "https://developers.google.com/static/crawling/ipranges/"
AGENTS = {  # token: (operator, what it does, the operator's address list or None)
    "GPTBot": ("OpenAI", "training", "https://openai.com/gptbot.json"),
    "OAI-SearchBot": ("OpenAI", "search index", "https://openai.com/searchbot.json"),
    "ChatGPT-User": ("OpenAI", "user fetch", "https://openai.com/chatgpt-user.json"),
    "OAI-AdsBot": ("OpenAI", "ads check", "https://openai.com/adsbot.json"),
    "ClaudeBot": ("Anthropic", "training", "https://claude.com/crawling/bots.json"),
    "Claude-User": ("Anthropic", "user fetch", "https://claude.com/crawling/bots.json"),
    "Claude-SearchBot": ("Anthropic", "search index", "https://claude.com/crawling/bots.json"),
    "Claude-Agent": ("Anthropic", "hosted browser", "https://claude.com/.well-known/sail"),
    "PerplexityBot": ("Perplexity", "search index", "https://www.perplexity.ai/perplexitybot.json"),
    "Perplexity-User": ("Perplexity", "user fetch", "https://www.perplexity.ai/perplexity-user.json"),
    "Google-CloudVertexBot": ("Google", "owner-requested crawl", G + "special-crawlers.json"),
    "Google-GeminiNotebook": ("Google", "user fetch", G + "user-triggered-fetchers.json"),
    "Google-Agent": ("Google", "user agent", G + "user-triggered-agents.json"),
    "Applebot": ("Apple", "search index", "https://search.developer.apple.com/applebot.json"),
    "meta-externalagent": ("Meta", "training", None),
    "meta-webindexer": ("Meta", "search index", None),
    "meta-externalfetcher": ("Meta", "user fetch", None),
    "meta-externalads": ("Meta", "ads", None),
    "Amazonbot": ("Amazon", "training", "https://developer.amazon.com/amazonbot/ip-addresses/"),
    "Amzn-SearchBot": ("Amazon", "search index", "https://developer.amazon.com/amazonbot/searchbot-ip-addresses/"),
    "Amzn-User": ("Amazon", "user fetch", "https://developer.amazon.com/amazonbot/live-ip-addresses/"),
    "CCBot": ("Common Crawl", "training", "https://index.commoncrawl.org/ccbot.json"),
    "DuckAssistBot": ("DuckDuckGo", "user fetch", "https://duckduckgo.com/duckassistbot.json"),
    "MistralAI-User": ("Mistral", "user fetch", "https://mistral.ai/mistralai-user-ips.json"),
    "MistralAI-Index": ("Mistral", "search index", "https://mistral.ai/mistralai-index-ips.json"),
    "MistralAI-Training": ("Mistral", "training", None),
    "Bytespider": ("ByteDance", "training", None),
}
INSIDE_ONLY = {"Anthropic"}  # its list proves a request is Anthropic's, never that one is not


def address_lists():
    nets = defaultdict(list)
    for url in {a[2] for a in AGENTS.values() if a[2]}:
        req = urllib.request.Request(url, headers={"User-Agent": "Mozilla/5.0"})
        text = urllib.request.urlopen(req, timeout=60).read().decode("utf-8", "ignore")
        text = re.sub(r"(?is)<script.*?</script>", "", text)  # Amazon's pages print YOUR address in a script
        for m in re.findall(r"[0-9a-fA-F:.]{7,}/\d{1,3}|\b\d{1,3}(?:\.\d{1,3}){3}\b", text):
            try:
                net = ipaddress.ip_network(m, strict=False)
            except ValueError:
                continue
            for op in {a[0] for a in AGENTS.values() if a[2] == url}:
                nets[op].append(net)
    return nets


def verdict(op, ip, cloudflare_label, nets, operators_at_address):
    if cloudflare_label or any(ipaddress.ip_address(ip) in n for n in nets.get(op, [])):
        return "passed"
    if nets.get(op) and op not in INSIDE_ONLY:
        return "failed"
    if operators_at_address > 1:  # one address cannot be two companies' crawler
        return "failed"
    return "unresolved"


def cloudflare(zone, start, end):
    q = """query($z:String!,$a:Time!,$b:Time!,$f:[ZoneHttpRequestsAdaptiveGroupsFilter_InputObject!]){
      viewer{zones(filter:{zoneTag:$z}){httpRequestsAdaptiveGroups(limit:10000,
        filter:{datetime_geq:$a,datetime_lt:$b,OR:$f}){count dimensions{date clientRequestHTTPHost
        clientRequestPath userAgent clientIP edgeResponseStatus verifiedBotCategory}}}}}"""
    f = [{"userAgent_like": f"%{t}%"} for t in AGENTS] + [{"verifiedBotCategory_like": "AI%"}]
    day, rows = datetime.date.fromisoformat(start), []
    while day < datetime.date.fromisoformat(end):
        v = {"z": zone, "a": f"{day}T00:00:00Z", "b": f"{day + datetime.timedelta(days=1)}T00:00:00Z", "f": f}
        req = urllib.request.Request("https://api.cloudflare.com/client/v4/graphql", method="POST",
                                     data=json.dumps({"query": q, "variables": v}).encode(), headers={
                                         "Authorization": "Bearer " + os.environ["CF_API_TOKEN"],
                                         "Content-Type": "application/json"})
        res = json.load(urllib.request.urlopen(req, timeout=120))
        if res.get("errors"):
            sys.exit(res["errors"])
        groups = res["data"]["viewer"]["zones"][0]["httpRequestsAdaptiveGroups"]
        if len(groups) == 10000:
            print(f"{day}: 10,000 groups, the limit; split the day into hours")
        for g in groups:
            d = g["dimensions"]
            rows.append((d["date"], d["clientRequestHTTPHost"], d["clientRequestPath"], d["edgeResponseStatus"],
                         d["userAgent"], d["clientIP"], d["verifiedBotCategory"], g["count"]))
        day += datetime.timedelta(days=1)
    return rows


def railway(path):
    rows = []
    for line in open(path):
        if line.startswith("{"):
            r = json.loads(line)
            rows.append((r["timestamp"][:10], r["host"], r["path"].split("?")[0], r["httpStatus"],
                         r.get("clientUa", ""), r["srcIp"], "", 1))
    return rows


def main():
    rows = cloudflare(*sys.argv[2:5]) if sys.argv[1] == "cloudflare" else railway(sys.argv[2])
    nets, out, week, claims = address_lists(), Counter(), defaultdict(Counter), defaultdict(set)
    for r in rows:
        token = max((t for t in AGENTS if t.lower() in r[4].lower()), key=len, default=None)
        if token:
            claims[r[5]].add(AGENTS[token][0])
    for day, host, path, status, ua, ip, label, n in rows:
        token = max((t for t in AGENTS if t.lower() in ua.lower()), key=len, default=None)
        if token:
            op, kind, _ = AGENTS[token]
        elif label:
            op, kind = "(Cloudflare: " + label + ")", "unnamed"
        else:  # no AI name: keep it only if it came from an operator's own addresses
            op = next((o for o, ns in nets.items() if any(ipaddress.ip_address(ip) in x for x in ns)), None)
            if not op:
                continue
            kind = "unnamed, from " + op + "'s addresses"
        v = verdict(op, ip, label, nets, len(claims[ip]))
        out[(day, host, path, status, token or ua[:60], op, kind, label, len(claims[ip]), v)] += n
        week[token or op][v] += n
        week[token or op][f"status {status}"] += n
    with open("ai-bot-week.csv", "w", newline="") as fh:
        w = csv.writer(fh)
        w.writerow(["day", "host", "path", "status", "agent", "operator", "kind", "cloudflare_label",
                    "operators_at_address", "verdict", "requests"])
        w.writerows(k + (n,) for k, n in sorted(out.items()))
    for agent, c in sorted(week.items(), key=lambda x: -sum(v for k, v in x[1].items() if "status" not in k)):
        total = sum(v for k, v in c.items() if not k.startswith("status"))
        print(f"{agent:22} {total:7}  " + "  ".join(f"{k} {v}" for k, v in sorted(c.items())))


main()
Run it with your zone ID, the window’s first day and the day after its last, soon after the week ends, because it checks old requests against today’s address files:
python3 ai_bot_week.py cloudflare ZONE_ID 2026-10-23 2026-10-30If a day prints “10,000 groups, the limit; split the day into hours”, that day came back short, and splitting it means changing the script’s one-day step to hours. We reran the script as printed on 13 November, on one of our domains for 6 to 12 November: 14 seconds, and 726 of 861 named requests failed 1.
Step 4: Read each name against its address check
The script gives every request one of three outcomes:
Our twelve domains split like this:
Scroll horizontally to see all columns when the table is wider than this page.
| Outcome | Requests | Share |
|---|---|---|
| Passed the address check | 6,438 | 48% |
| Failed it | 6,902 | 51% |
| Unresolved | 102 | 1% |
| Named an AI agent | 13,442 |
Report the two kinds of failure separately. 4,920 requests, 37% of those named, came from outside every range their operator publishes. The other 1,982 named Anthropic or ByteDance crawlers, which no address file can rule out. They failed because one address claimed two companies’ crawlers, and at least one claim must be false 1.
Applebot sent 6,074 named requests and 5,598 passed, most of our passing total. Without Applebot, 840 of 7,368 passed. Name by name:
Share of Each Crawler Name’s Requests That Passed the Address Check
Our own domains through Cloudflare, 23 to 29 October 2026, names with 100 or more requests
6,074 named92.2%
794 named44.1%
744 named31%
565 named20.7%
577 named15.1%
589 named2.2%
483 named0.8%
501 named0.4%
584 named0%
534 named0%
495 named0%
493 named0%
493 named0%
480 named0%
View the data
| Label | Value |
|---|---|
| Applebot 6,074 named | 92.2% |
| ClaudeBot 794 named | 44.1% |
| OAI-SearchBot 744 named | 31% |
| Amazonbot 565 named | 20.7% |
| GPTBot 577 named | 15.1% |
| Bytespider 589 named | 2.2% |
| PerplexityBot 483 named | 0.8% |
| ChatGPT-User 501 named | 0.4% |
| Claude-User 584 named | 0% |
| OAI-AdsBot 534 named | 0% |
| CCBot 495 named | 0% |
| DuckAssistBot 493 named | 0% |
| Perplexity-User 493 named | 0% |
| Claude-SearchBot 480 named | 0% |
The chart shows eleven names from seven companies each landing 480 to 590 requests. Close totals prove nothing, but they sent us to the operators_at_address column, the count of companies one address claimed: 6,867 named requests came from an address claiming two or more.
Step 5: Read what each group asked for and what it got
This table splits the same requests by the path they asked for:
Scroll horizontally to see all columns when the table is wider than this page.
| What was asked for | Passed | Failed | Unresolved |
|---|---|---|---|
| Pages | 5,712 | 1,701 | 77 |
| Secret or config files (.env, .git, backups) | 0 | 4,497 | 0 |
| App, admin, login or API paths | 0 | 508 | 0 |
| robots.txt | 474 | 29 | 24 |
| Home page | 180 | 54 | 0 |
| Sitemap | 42 | 53 | 0 |
| Images, scripts, fonts | 30 | 60 | 1 |
Of the 4,497 requests that used an AI crawler’s name to ask for password and config files, not one passed the address check.
Where an operator publishes no addresses, the path is the next clue: a request calling itself Bytespider asked for /@fs/home/ubuntu/.aws/credentials, a file no crawler needs. People who run their own servers read these requests the same way:
Tips from Reddit
What self-hosters see in the same requests
The background noise of scanners trying to find exploitable sites usually hit 404s on predefined paths and paths that don't take a lot of processing.
These are not AI agents, they are spoofers. They search the entire internet for known vulnerabilities.
Then read the status, the code the server sent back. Our domains redirect everyone, so every passing crawler got the 301 a person gets. All 229 requests refused with a 403 had failed, nearly all on app and admin paths of domains with no app.
Our bot settings were all off, and the Free plan’s analytics would not say which rule sent those 403s. The counts are sampled estimates. A rerun moved single rows by one, so round them in a report.
Step 6: Read the agents the script does not name
The script also keeps every request Cloudflare labels as AI, because names typed in by hand fall behind. That added 383 requests, 382 of them under names the script did not carry: PetalBot, Reflectionbot, ShapBot and GoogleOther, a generic crawler Google’s product teams use 6. Each is an allow-or-ignore decision.
The remaining one had an ordinary Chrome-on-Linux user agent and no crawler name. Cloudflare labelled it “AI Assistant”, so the script kept it, where a name filter would have dropped it. This route catches such an agent only when Cloudflare labels it.
Reading a Week From Your Host’s Raw Logs
Cloudflare sees only what it sits in front of. A host whose logs keep each request’s user agent and address feeds the same script, with the same three outcomes.
Step 7: Export the host’s week
On Railway, with its command-line tool signed in, pull the service’s request logs for the week, using your own project ID and service name.
railway logs --http --project YOUR_PROJECT_ID --service web --environment production --since 2026-10-23T00:00:00Z --until 2026-10-30T00:00:00Z --lines 5000 --json > host-week.jsonlRailway refuses --lines 10000 with “Error in beforeLimit - Invalid input” (still true on 13 November), so pull a busy week in parts. After a midweek redeploy, the earlier days sit with the older deployment.
Step 8: Run the same script on it
The same script reads the exported file:
python3 ai_bot_week.py railway host-week.jsonlOur host route ran on one of our internal tools: 451 requests that week, none naming an AI agent or coming from an operator’s address. Its robots.txt tells every crawler to stay out, on purpose, and was fetched twice, both times under a desktop browser’s user agent. The log cannot say whether that rule kept AI crawlers away. It suits an internal tool and would hurt a marketing site.
Step 9: Send one AI read and find it in the log
A log with no AI requests may simply miss them, so test it first. Make up a path nobody links to, ask an AI assistant to open it, then pull that path and check it:
railway logs --http --project YOUR_PROJECT_ID --service web --environment production --path /your-made-up-path --since 1h --json > calibration.jsonl
python3 ai_bot_week.py railway calibration.jsonl
We asked Gemini, through Google’s Antigravity command-line tool, to open such a path on our tool. Within a second the log held three requests, none with a crawler name from any operator’s page 1:
Scroll horizontally to see all columns when the table is wider than this page.
| Request | User agent | Came from |
|---|---|---|
| GET | Google-Jetski-Antigravity | an address in Google’s published crawler ranges |
| HEAD | Go-http-client/2.0 | the laptop that asked the question |
| GET | Go-http-client/2.0 | the laptop that asked the question |
None asked for robots.txt first, and Google says its user-triggered fetchers “generally ignore robots.txt rules” 7. On the host route the script keeps a request from an operator’s addresses under any name, so Google’s line passed. The other two came from our laptop under a code library’s name, and nothing marks them as AI, so a log undercounts AI reads.
A log also never shows what a crawler made of the page it got. The playbook below covers that side, so every release ships pages AI crawlers can reach and read.
Turning the Week Into Fixes With Owners
Before a row becomes a fix, read its address check and its path together:
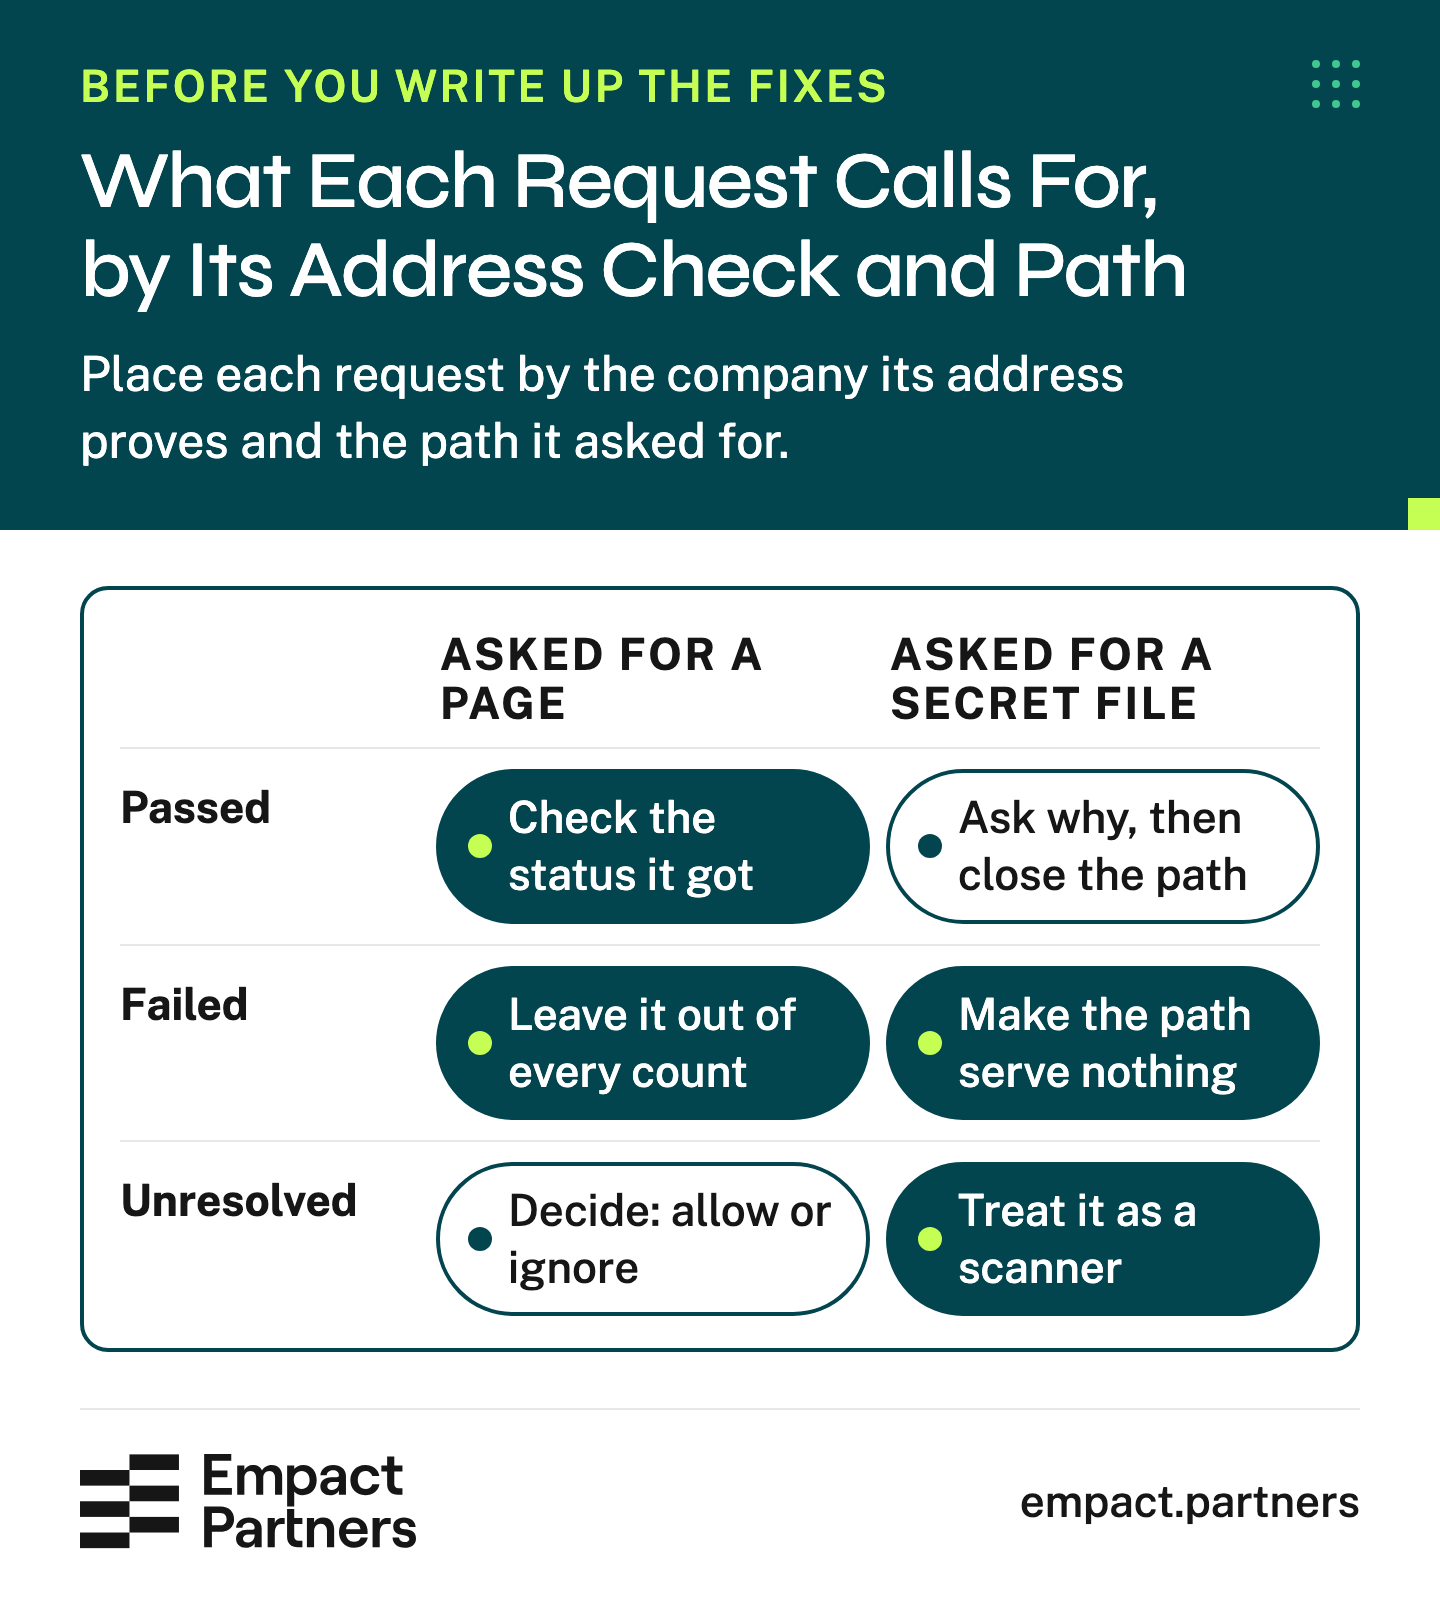
A crawler name alone never justifies a rule. Our week’s fixes, straight from the sheet:
Scroll horizontally to see all columns when the table is wider than this page.
| Finding | Intended? | Owner | Check next week |
|---|---|---|---|
| Crawlers that passed got the redirect everyone gets | Yes, the domains are retired | nobody | passed rows still redirect |
| 229 blocks, all on failed requests, mostly app and admin paths | Harmless, though the Free plan would not name the rule | nobody, leave it | no passed row among the blocks |
| 4,497 named requests for secret files, all failed | Nothing to fix behind a redirect | engineering, on a live site | those paths answer 404 |
| 2,071 “live AI fetches” by name, 2 passed | Not a site fault | whoever reports AI traffic | AI counts drawn from passed rows, unresolved shown apart |
| 383 AI-labelled requests the script did not name | Not a fault | whoever runs the check | each name decided and dated in the script |
| No AI crawler on the host | The rule is intended, its effect unknown | nobody | robots.txt unchanged |
Half the rows say leave it alone, so mark each row intended or a fault before engineering sees it, or engineers chase scanners.
A live marketing site can show rows our retired domains could not:
Rows that need a fix on a live site
- A search crawler such as OAI-SearchBot passed and got a 403 or a challenge. The CDN owner adds an exception for verified bots
- A passing crawler got a 200 on a page whose text appears only after scripts run, a rendering job no CDN rule fixes
- A training crawler nobody chose to allow or block, a policy call first: OpenAI says each of its settings “is independent of the others” 2
- A robots.txt change rechecked the same day, when OpenAI says about 24 hours and Perplexity up to 24 2 5
- A secret-file request that gets anything but a 404
We found the rule and rendering rows on four partner sites we reviewed between August and October, reading each robots.txt and what each page serves without scripts. None had blocked an AI crawler by name 14, the fix a bot count prompts, yet each had its own fault.
One robots.txt shut a section to every crawler, and one site had no robots.txt at all. One price loaded only after scripts ran, and one site’s canonical tags (naming a page’s preferred address) pointed at redirects.
My own rule from that week and those reviews:
Check the address before a count goes into a report or a block goes into a rule. Keep the unresolved rows visible instead of rounding them into a total. A rule written against a crawler’s name blocks the real crawler along with every scanner borrowing it.
 Vlad Shvets on LinkedInOpens in a new tab
Whether crawlers could read what they found is a separate check, and it needs no log access. Give the free GEO Audit below your website’s address, and it reports the robots rules your site sets for AI crawlers and what AI engines read without JavaScript.
Do AI Crawler Visits Lead to Citations?
A clean week shows which AI crawlers reached your pages and what each got back. It cannot show whether ChatGPT, Google AI Mode or Claude names you when a buyer asks, since a crawler can fetch a page daily with no answer quoting it. Citations are measured differently: ask the engines your buyers’ questions and read the sources they give.
We read those sources in the Empact Panel, a tool we built. Every week it puts the questions a partner’s buyers ask to Claude, ChatGPT and Google AI Mode, then saves each answer and the pages behind it.
One partner’s card shows what no log can: which of its own pages answers cite. Over 90 days, answers cited 184 of its pages, and 97 were neither landing pages nor blog posts, so a crawl check of the marketing pages alone misses most of them. Its own pages were 3.8% of all sources cited, and the rest came from other sites.
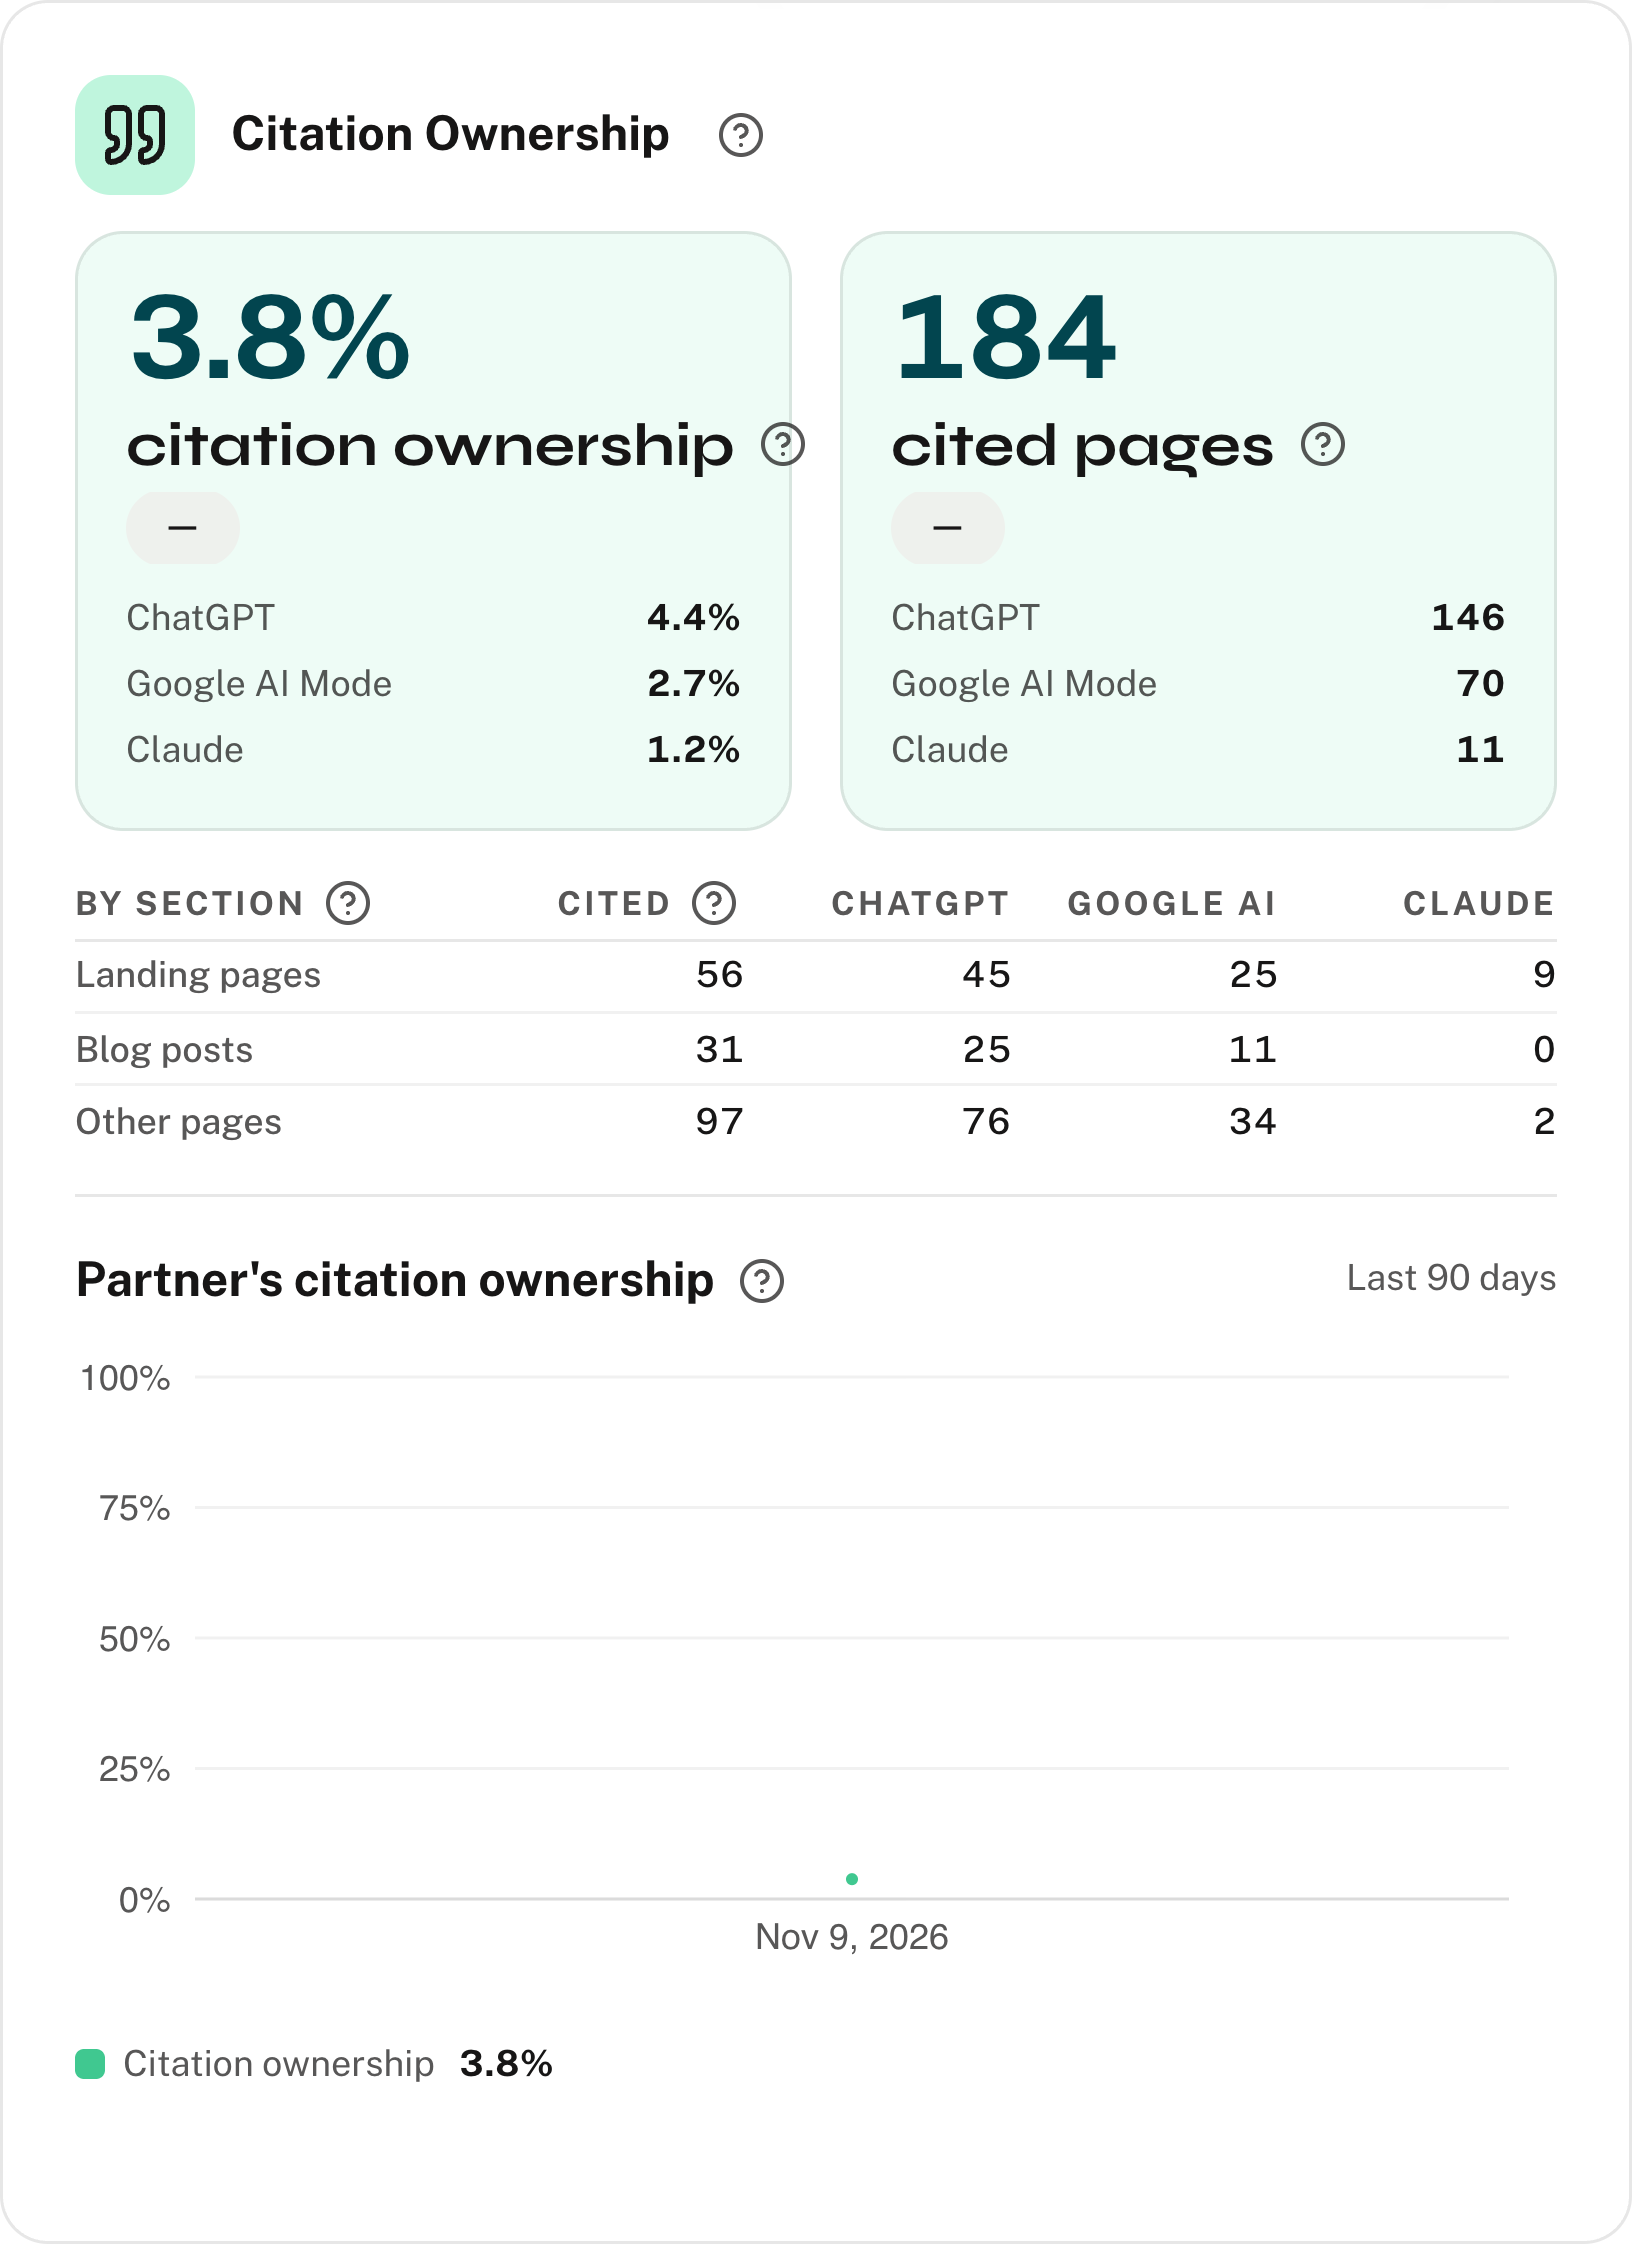
So judge each fix twice, in the logs and in the answers. After any robots.txt or CDN change, wait a full day, re-read the operators’ pages and pull the next week. The answers take longer to move.
With your site, our first look would skip the bot names. It would go to what keeps pages from being read, such as refused search crawlers and pages whose text arrives only after scripts run.
What our crawl-access work covers
- A week of your Cloudflare or host requests, each AI crawler name checked against its operator’s addresses where they are published
- Your robots.txt and the text your key pages serve without scripts
- Each recommendation with its first step
- If the check should run every week, an AI agent that runs it on your logs, owned by one person on your team
Frequently Asked Questions
If GPTBot visits our site every day, does ChatGPT recommend us?
No. A GPTBot line shows that something using that name fetched a page, and GPTBot is OpenAI’s training crawler, while ChatGPT’s search answers rely on OAI-SearchBot. Even a search crawler that passes the address check only proves the page was available. Whether ChatGPT names you shows up when you ask it your buyers’ questions and read its sources, so keep crawler reads and recommendations on separate lines of any report.
Can we run this check if our host keeps no request logs?
Not for any week already gone, because a request nobody recorded cannot be recovered. On 30 October 2026 Webflow offered no request log, and Vercel’s log drain began recording only on the day it was switched on. Put Cloudflare in front of the site, even on its Free plan, or turn on your host’s log drain, wait seven full days, then run the steps. Before you trust a zero from a new log, send one AI read to a made-up path and confirm the log caught it.
Should we block requests that use an AI crawler’s name from the wrong address?
No, not by the name, because a scanner switches names faster than anyone updates a rule, and a rule against GPTBot also stops the real GPTBot. Close the paths those requests hunt for instead, so .env files, .git folders and backup archives answer 404 to everyone. If an engineer still wants a block, base it on the address check and the path together, then confirm next week that no passing request landed inside it.
Is it safe to let every AI crawler into a SaaS marketing site?
Decide each kind on its own. A site that opts out of OAI-SearchBot will not be shown in ChatGPT search answers, OpenAI says, though it can still appear as a navigational link. Training crawlers such as GPTBot are a call for leadership and legal. Fetchers acting for a person may skip robots.txt, by Google’s, Meta’s and Amazon’s account. A sensible default is search crawlers allowed and training decided in writing.
Does a 200 response mean the crawler read our page?
A 200 means the server answered. If your price or product description is drawn by scripts after the page loads, a crawler that runs no scripts got an empty frame with that 200. Open the page source, not the rendered page, and search it for the sentence you want quoted. If it is missing, a crawler that runs no scripts never received it. That is a rendering fix for engineering, and no robots.txt line changes it.
How long after a robots.txt change should we check the logs again?
At least a full day, and preferably the whole following week. OpenAI says a robots.txt change can take about 24 hours to reach its search systems, and Perplexity says up to 24 hours for its settings. A same-afternoon check shows crawlers still acting on the old file and sends the team after a fix that has not had time to land. A CDN rule applies from the next request, but crawlers come back on their own schedule, so judge it on a week too.
Why does Google-Extended never show up in our logs?
Because it has no request string. Google says it crawls with its existing user agent strings and reads Google-Extended only as a robots.txt control. Its log count is always zero, and the token does not affect inclusion in Google Search. To see Google, look for Googlebot and the fetchers on Google’s address files: the host route checks those by address under any name, while the Cloudflare route sees only listed names and Cloudflare’s AI label.
Which team changes what once the fixes are written up?
Whoever runs Cloudflare owns the rules and any exception for verified bots. The web lead owns robots.txt and the page templates, and any text that loads after scripts. Whoever reports AI traffic owns the counting rule, so dashboards count only passed requests. Marketing orders the rows by which pages buyers need first, and whoever wrote each row checks it again the following week.
Do the agent names in the script stay current on their own?
The address files do, since the script downloads them fresh each run. The names do not: they sit in the file, and operators keep adding them. OpenAI, Meta, Amazon, Mistral, Perplexity and Google each changed a page or an address file between our 27 and 30 October reads, and on 13 November we added Claude-Agent. Re-read each operator’s page before a run, date your copy of the names, and add any name Cloudflare labels as AI.
Do AI agents that browse like a person show up in our logs at all?
Some do. Anthropic’s hosted browser adds Claude-Agent to an ordinary browser’s user agent and publishes its addresses, so the script can check it. Others send a browser’s user agent with no name. Cloudflare labelled one on our domains that week, and our triggered AI read wrote two lines under a code library’s name from the asking laptop. Read any log’s count as missing some AI reads.
Sources (14)
- Empact Partners, "AI crawler requests on twelve of our own Cloudflare zones, 23 to 29 October 2026" (2026)Empact Partners' own data↩1↩2↩3↩4↩5↩6one Railway host week and one calibration fetch, 30 October 2026; the printed script rerun on one zone, 13 November 2026.
- OpenAI, "Overview of OpenAI Crawlers" (2026)↩1
- Anthropic, "Does Anthropic crawl data from the web, and how can site owners block the crawler?" (2026)↩1
- Anthropic, "How do Anthropic-hosted browsers identify themselves when they browse the web on a user’s behalf?" (2026)↩1
- Perplexity, "Crawlers" (2026)↩1
- Google Search Central, "Google’s common crawlers" (2026)↩1↩2↩3
- Google Search Central, "Google User-Triggered Fetchers" (2026)↩1↩2
- Apple, "About Applebot" (2026)↩1↩2
- Meta, "Web Crawlers" (2026)↩1
- Amazon, "Web Search crawlers" (2026)↩1
- Common Crawl, "CCBot" (2026)↩1
- DuckDuckGo, "Is DuckAssistBot related to DuckDuckGo?" (2026)↩1
- Mistral AI, "Mistral crawlers" (2026)↩1
- Empact Partners, "four partner site audits run by our consultants, August to October 2026" (2026)Empact Partners' own data↩1each reading the site’s robots.txt and the text its pages serve without scripts. No partner named.
Keep reading
GEO Should Your Team Write LinkedIn Articles for AI Search?
Check whether your buyers’ AI engine cites LinkedIn, then write the article under the right name and track it every week.
GEO How to Find and Fix Your SaaS Brand’s GEO Gaps
Check whether AI answers name your SaaS, identify the gaps, and decide what to fix with a practical GEO plan.
GEO How Fast AI Engines Notice New Mentions and Why Some Fixes Lag
ChatGPT can cite a new page within a week and still use a company's old name for months. Here is how to tell which clock an answer runs on.