How to Measure AI Visibility Engine by Engine
Separate brand mentions from source citations, compare engines fairly, and choose where your next quarter's AI-search work goes.
On this page
Empact Newsletter
One email a month on what is working in AI search and SaaS go-to-market.
An AI visibility number counts how often something turns up in AI answers to your buyers’ questions, such as your brand’s name or a link to a source you care about. Some dashboards show one such number for all engines, even though each engine reads a different part of the web. The blend hides how far apart they sit, and once you split it, the lowest engine looks like the place to start even when your planned work would never show up there.
Empact Partners works engine by engine when it gets a SaaS product recommended in AI answers, since the Reddit thread that lands in Google AI Mode may never reach Claude. A blended number hides exactly that.
One partner’s Empact Panel, the record we built to keep each engine’s weekly answers apart, shows the problem. In its B2B software category, Reddit appears in 6.3% of cited answers with the engines pooled.1 Read separately, Google AI Mode cites it in about 13%, ChatGPT in under 1% and Claude in none.
How a Blended AI Visibility Number Is Weighted
A dashboard that blends engines pools the cited answers from every engine, counts the ones that cite the source you track and divides. The result is a weighted average, and the weights are how many answers each engine contributed. Whoever set up the tracking chose those weights when they decided how many questions each engine gets.
This panel asks Claude 300 questions a week and each of the other two engines 5,000. So the pooled figure leans on ChatGPT and Google AI Mode, and comes to 6.3% of 39,939 cited answers over four weeks.
Give each engine an equal say over the four weeks and the same answers give 4.3%. Take each engine’s median week and average the three, and they give 4.6%. All three come from the same answers, and none is close to what any one engine shows. The chart puts the weekly blend beside each engine’s own line.
Reddit’s Share of Cited Answers, Week by Week
One partner’s Empact Panel, a B2B software category, 15 Oct to 5 Nov 2026; Claude asked 300 questions a week, the others 5,000
View the data
| Label | Google AI Mode | ChatGPT | Claude | All three blended |
|---|---|---|---|---|
| Oct 15 | 13.2% | 0.9% | 0% | 6.6% |
| Oct 22 | 13.6% | 1.3% | 0% | 7% |
| Oct 29 | 10.8% | 0.5% | 0% | 5.3% |
| Nov 5 | 12.9% | 0.3% | 0% | 6.2% |
Every week the blend sat between 5.3% and 7.0%, a band no engine visited. Google AI Mode moved between 10.8% and 13.6%, ChatGPT between 0.3% and 1.3%, and Claude stayed at zero. Unless your buyers happen to split their questions 5,000, 5,000 and 300 between the engines, the blended line describes nobody you sell to.
How to Read Each Engine on Its Own
Reading each engine on its own starts with five settings. Each one changes the number, so write them down before the first run:
- Ask every engine you compare the same questions, in separate runs on the same weekday
- Pick the denominator by question: every answer for “are we named?”, only the answers with sources for “what does this engine read?”
- Keep the zeros, so an answer that cited sources, none of them the one you track, stays in the count
- Log failed or refused runs apart, since they are not zeros, and keep answers with no sources out of any source question’s count
- Report each engine as the median of its last four weekly rates, and compare it with the range those rates covered before the work began
Get the third and fourth settings wrong and the figure moves. In the week to 15 October, 314 of Google AI Mode’s 5,000 answers on this panel cited nothing. Counted as zeros, they put Reddit’s share at 12.3%. Left out, it reads 13.2%, because an answer with no sources says nothing about what the engine reads.
Claude is the opposite case. Of its 1,200 answers over the four weeks, 1,196 cited at least one source and none of them cited Reddit, so they are 1,196 recorded zeros and they stay. The other four, one a week, cited nothing and sit outside the count as missing.
Each row of the log carries these fields, whether a panel fills it or a person does it by hand:
Scroll horizontally to see all columns when the table is wider than this page.
| Field | What to record | Why it changes the reading |
|---|---|---|
| Question and group | The exact wording, and the product line or topic it belongs to | An engine’s number moves with the mix of questions behind it |
| Engine and surface | The product and how you reached it, such as ChatGPT’s app, Google’s AI Mode results or Claude through its API with web search | Two readings of “ChatGPT” disagree when the surface differs |
| Country and date | Where the question was asked from, and the week | Answers differ by country, and medians are taken week by week |
| Sources cited | Every address, or “none” | “None” is missing for a source question |
| Tracked source present | Yes or no, only for answers that cited something | This is the zero that counts |
| Brand named | Yes or no, for every answer collected | Being named uses every answer, cited or not |
| Run status | Collected, failed or refused | A failed run is missing data |
Single questions are unsteady. Of the 4,992 questions Google AI Mode answered with sources at least once on this panel, 61 cited Reddit in all four weeks, 523 in two or three, 920 in only one and 3,488 in none. So report each engine as a weekly rate, the share of that week’s cited answers that cite Reddit. Then use the median of the last four weeks, which no single question can swing much.
Two practitioners in an r/TechSEO thread about building a tracker add a field to that log, and say what they do with the citations once they have them:
Tips from Reddit
From practitioners building their own trackers
One thing I'd add to the five runs per engine: log whether the answer actually triggered a web search. A run that answers from the model's own memory and a run that searched and cited pages are measuring two different things, and averaging them blurs both.
whats worked for me so far is reverse engineering the citations, so looking at what pages each engine cites for my prompts and then getting placements on those sites / listicles.
A team without a panel can keep this log in a spreadsheet, one row per answer, filled on the same weekday. Our AI visibility baseline sheet gives each of ChatGPT and Google AI Mode its own rows, and reading Claude too means adding a third set. How many questions a reading needs is the other half of the method. With a smaller set, you need more weeks before a change in the weekly share is bigger than its usual swing.
If you would rather see your own brand split by engine before building a log, the free report below runs a first reading on two of the three engines:
Why the Question Mix Moves Each Engine’s Number
Change the questions and an engine’s figure changes too. This panel’s questions cover three product lines, with 3,000 questions on the largest and 1,000 on each of the other two. Claude is asked 100 from each. Google AI Mode cites Reddit in 10.7% of its cited answers on the largest line, 17.8% on the second and 13.1% on the third.
Because the largest line holds three questions in five, AI Mode’s overall 12.6% leans toward its lowest group. Weight the three lines equally and the same answers read 13.9%. ChatGPT barely moves by line, between 0.7% and 0.9%, and Claude reads zero on all three. The chart sets the three product lines side by side for each engine.
Reddit’s Share of Cited Answers by Product Line
Four weekly runs pooled, one partner’s Empact Panel, 15 Oct to 5 Nov 2026
View the data
| Label | Google AI Mode | ChatGPT | Claude |
|---|---|---|---|
| Largest product line | 10.7% | 0.7% | 0% |
| Second product line | 17.8% | 0.7% | 0% |
| Third product line | 13.1% | 0.9% | 0% |
So read each engine by question group as well as overall. A question set that leans on one product line tilts every engine’s number built on it.
A fair worry about Claude is that its zero comes from asking it fewer questions. Its 300 questions include 245 that the other two engines were also asked. On those, Google AI Mode cited Reddit in 101 of 917 cited answers and ChatGPT in 3 of 979.
Claude cited Reddit in none of its 1,196 cited answers, on those questions or any other, through its API with web search in these four weeks. On the questions all three were asked, the other two cited Reddit and Claude never did, so asking Claude fewer questions does not look like the reason. The next step is to see what it cites instead.
Which Kinds of Pages Each Engine Cites
Among every page the three engines cited on this panel over the four weeks, we counted three kinds, community platforms (Reddit, LinkedIn and YouTube), companies’ own front pages, and “best of” listicles or comparison pages, and set the rest aside. The table shows how often each kind turns up in each engine’s cited answers.
Scroll horizontally to see all columns when the table is wider than this page.
| Engine | Reddit, LinkedIn or YouTube | A company’s own front page | A listicle or comparison page (at least) |
|---|---|---|---|
| Google AI Mode | 20.8% | 4.5% | 56.5% |
| ChatGPT | 1.6% | 75.8% | 60.6% |
| Claude | 0.2% | 1.8% | 98.9% |
A listicle or comparison page here is one whose address names a best-of or top roundup, alternatives or a comparison, so the last column is an estimate from addresses. In a sample of 40 pages the rule matched, 38 were product listicles or comparisons. The rule misses listicles with other addresses. For each engine, the cell to remember is the kind of page it cites far more often than the other two do:
On Google AI Mode, those community pages are mostly Reddit and YouTube. Beside its listicles, Claude cites Wikipedia, in 5.9% of its cited answers against about 0.1% for the other two, and it barely cites community platforms at all. When we asked Claude’s web search to search reddit.com on 28 October, it returned an error saying the domain was not accessible to its user agent.3
Listicles and comparison pages are the only kind all three engines cite often. So the work outside your own site falls into two kinds:
- Community content: Reddit threads, LinkedIn posts and YouTube videos. On this panel they reach Google AI Mode, and almost never ChatGPT or Claude.
- Third-party mentions: other sites writing about a brand, listicles and comparison pages first. On this panel they reach all three engines.
For the second kind, our playbook walks you through finding the pages Google AI Mode and ChatGPT cite in your category that never mention you, and getting your product added to them:
Which Engine to Work on First
The lowest number on a per-engine report pulls the eye, and on this panel it is Claude’s zero for Reddit. Aiming Reddit work at Claude would spend a quarter on an engine that cited Reddit in none of 1,196 answers. Its web search would not even open Reddit in our test.
Claude cited Reddit in none of 1,196 answers on this panel, but it cited a listicle or comparison page in almost every one.
So the first engine comes from three inputs instead, checked in the order the drawing shows:
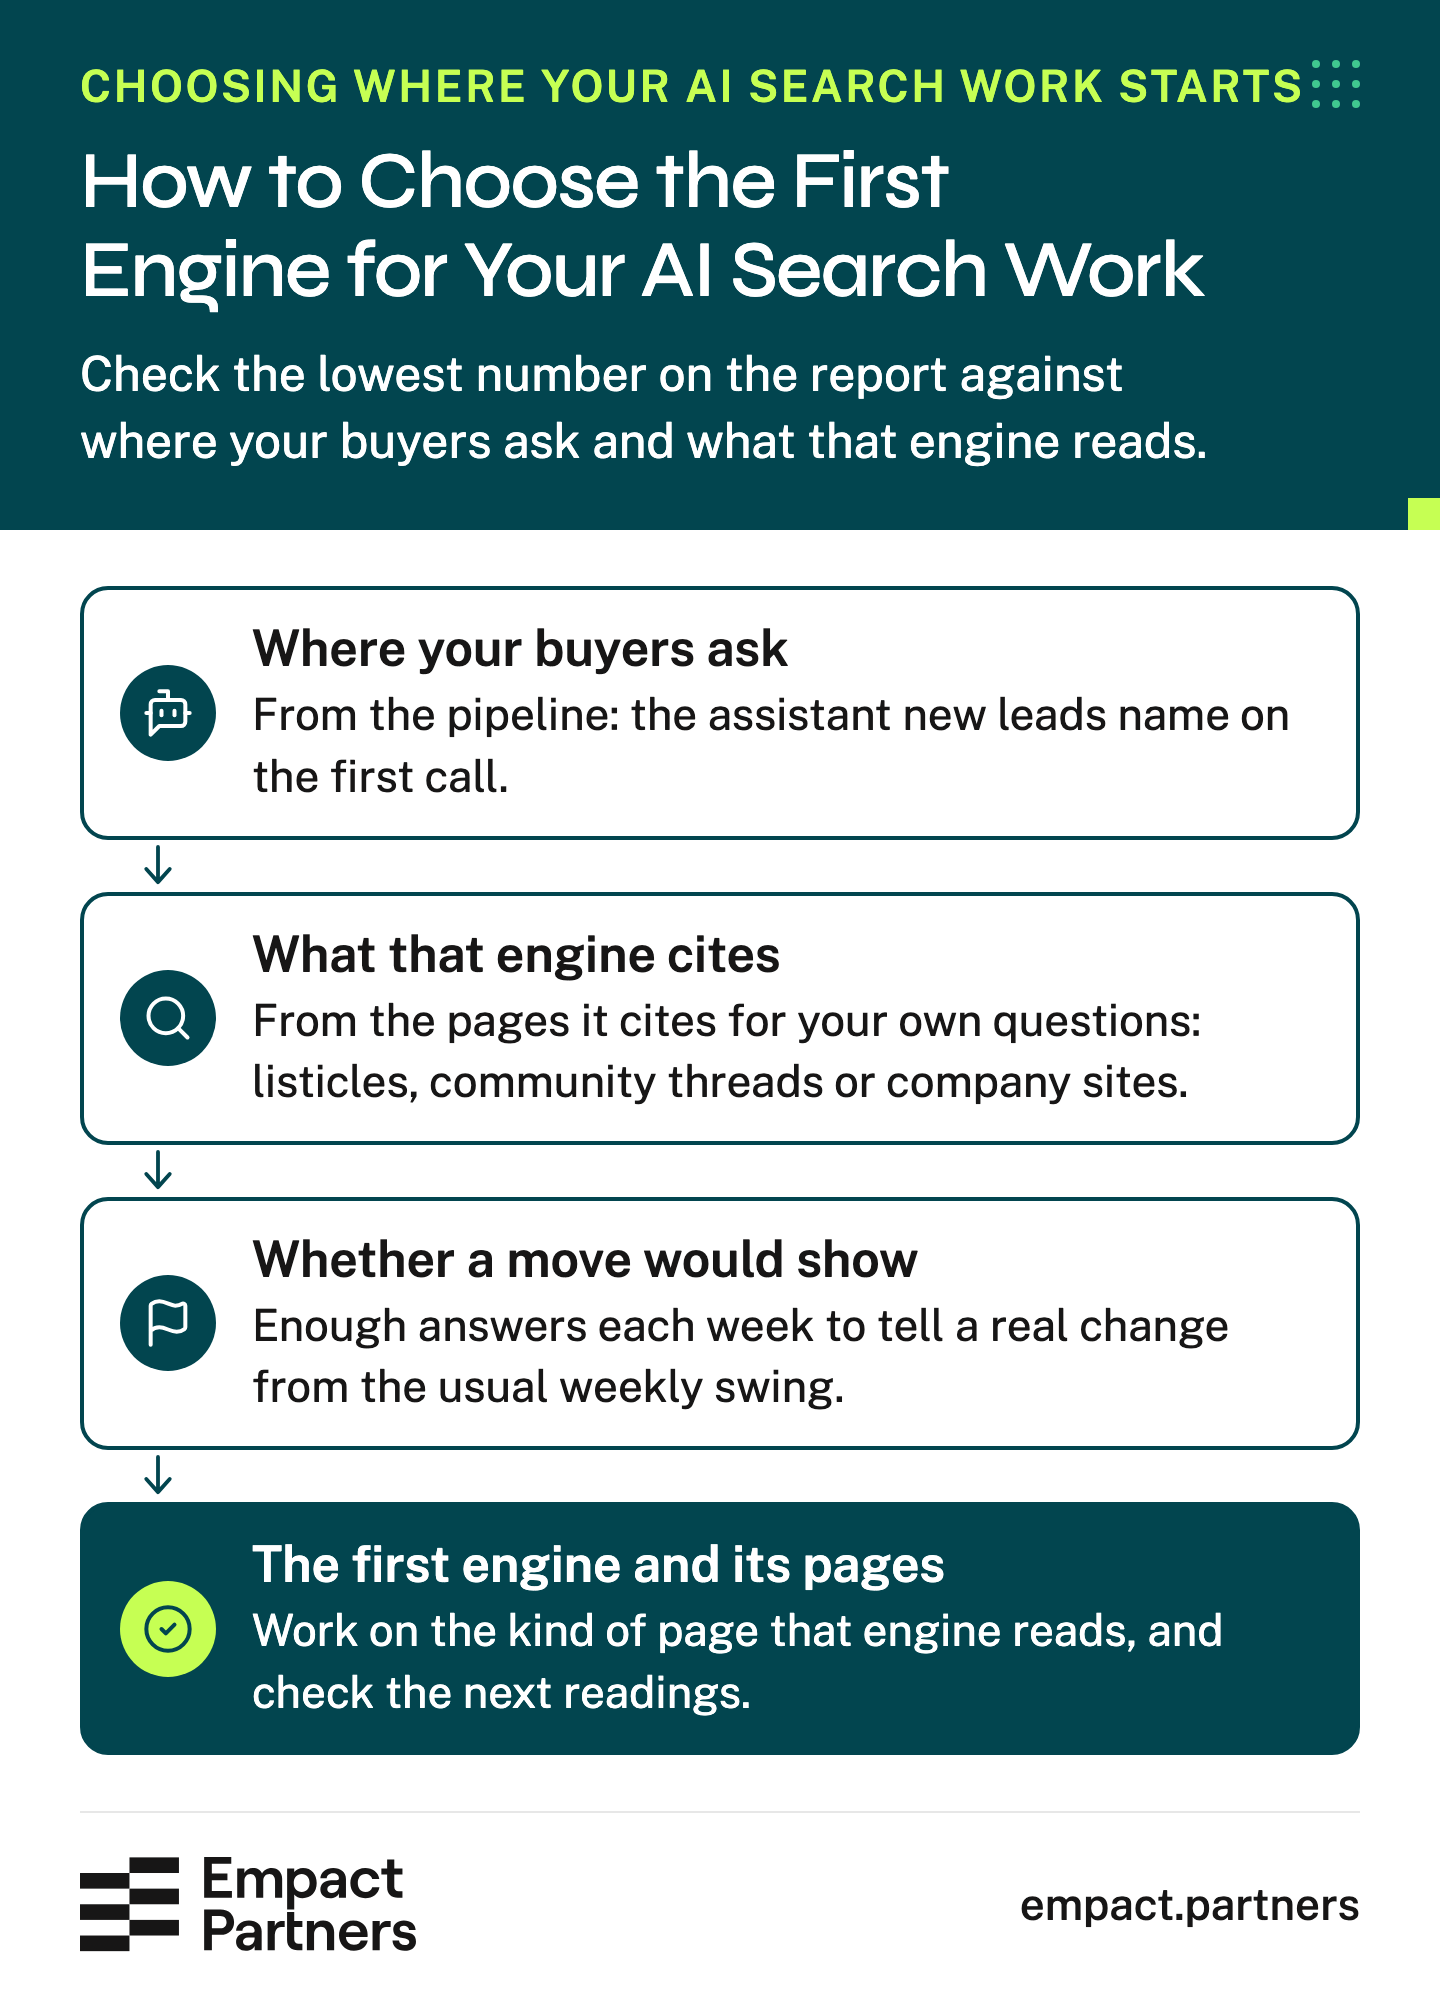
Each input has a source your team can check:
- Where your buyers ask: new leads say which assistant they used on the first call, and the answer goes into the CRM
- What that engine reads: the source count from your own questions shows which kinds of page reach it
- Whether a move would show: you ask that engine enough of your questions each week to tell a real change from its usual weekly swing
On this panel, the source count points to the kind of page. All three engines cite listicles and comparison pages often, so whichever engine this partner’s buyers use, getting named on the ones the answers cite is the first thing to test. Which engine leads still depends on where this partner’s buyers ask, which its pipeline records can show.
A September test on a panel we run for another partner points the same way, though what it shows is an association, and listicles may partly favor vendors the engines already liked.2 ChatGPT named a vendor in 52.6% of its answers when a cited roundup listed it, against 11.2% when no cited roundup did. Claude did the same in 46.6% against 10.7%.
On this panel, Reddit work comes second unless the partner’s buyers mostly use Google AI Mode, because it reaches that engine and little else. Vlad Shvets, who founded Empact Partners, puts the whole choice this way:
I’d pick the first engine from where your buyers ask and what that engine cites. The lowest number on the report can belong to an engine your planned work can’t reach. Spend a quarter there and the report won’t move, however good the work was.
 Vlad Shvets on LinkedInOpens in a new tab
Once the work starts, test the choice of engine and page. Split your questions into the ones whose cited listicles now name you and the ones whose listicles do not. Read each engine on both halves, and compare each half with its readings from before the work.
If naming rises on the first half and holds on the second, that is evidence the listicle work helped, though the halves may differ in other ways. If one engine stays flat while the others rise, check whether the listicle work reaches that engine before you add more of it.
Report Each Engine on Its Own Row
The board will ask for one number anyway. Give it the range with each engine named. On this panel, that means saying Reddit appears in none of Claude’s cited answers, under 1% of ChatGPT’s and about 13% of Google AI Mode’s. That sentence is barely longer than the blended one, and it shows which engine Reddit work can reach.
Each engine then gets its own row, with what it cites most and where to start:
Scroll horizontally to see all columns when the table is wider than this page.
| Engine | Reddit share, median of four weeks | What it cites most | Work first |
|---|---|---|---|
| Google AI Mode | 13.1% | Listicles and comparison pages, then Reddit and YouTube | Listicles, then the Reddit threads where buyers ask |
| ChatGPT | 0.7% | Companies’ front pages, then listicles | Listicles, then a front page that says plainly what you do |
| Claude | 0% | Listicles and comparison pages, then Wikipedia | Listicles and comparison pages |
The Empact Panel splits its cards by engine too. On this partner’s Reddit card for the last 90 days, the cited answers box counts, engine by engine, the answers that cited a Reddit thread the Panel checks for this category.
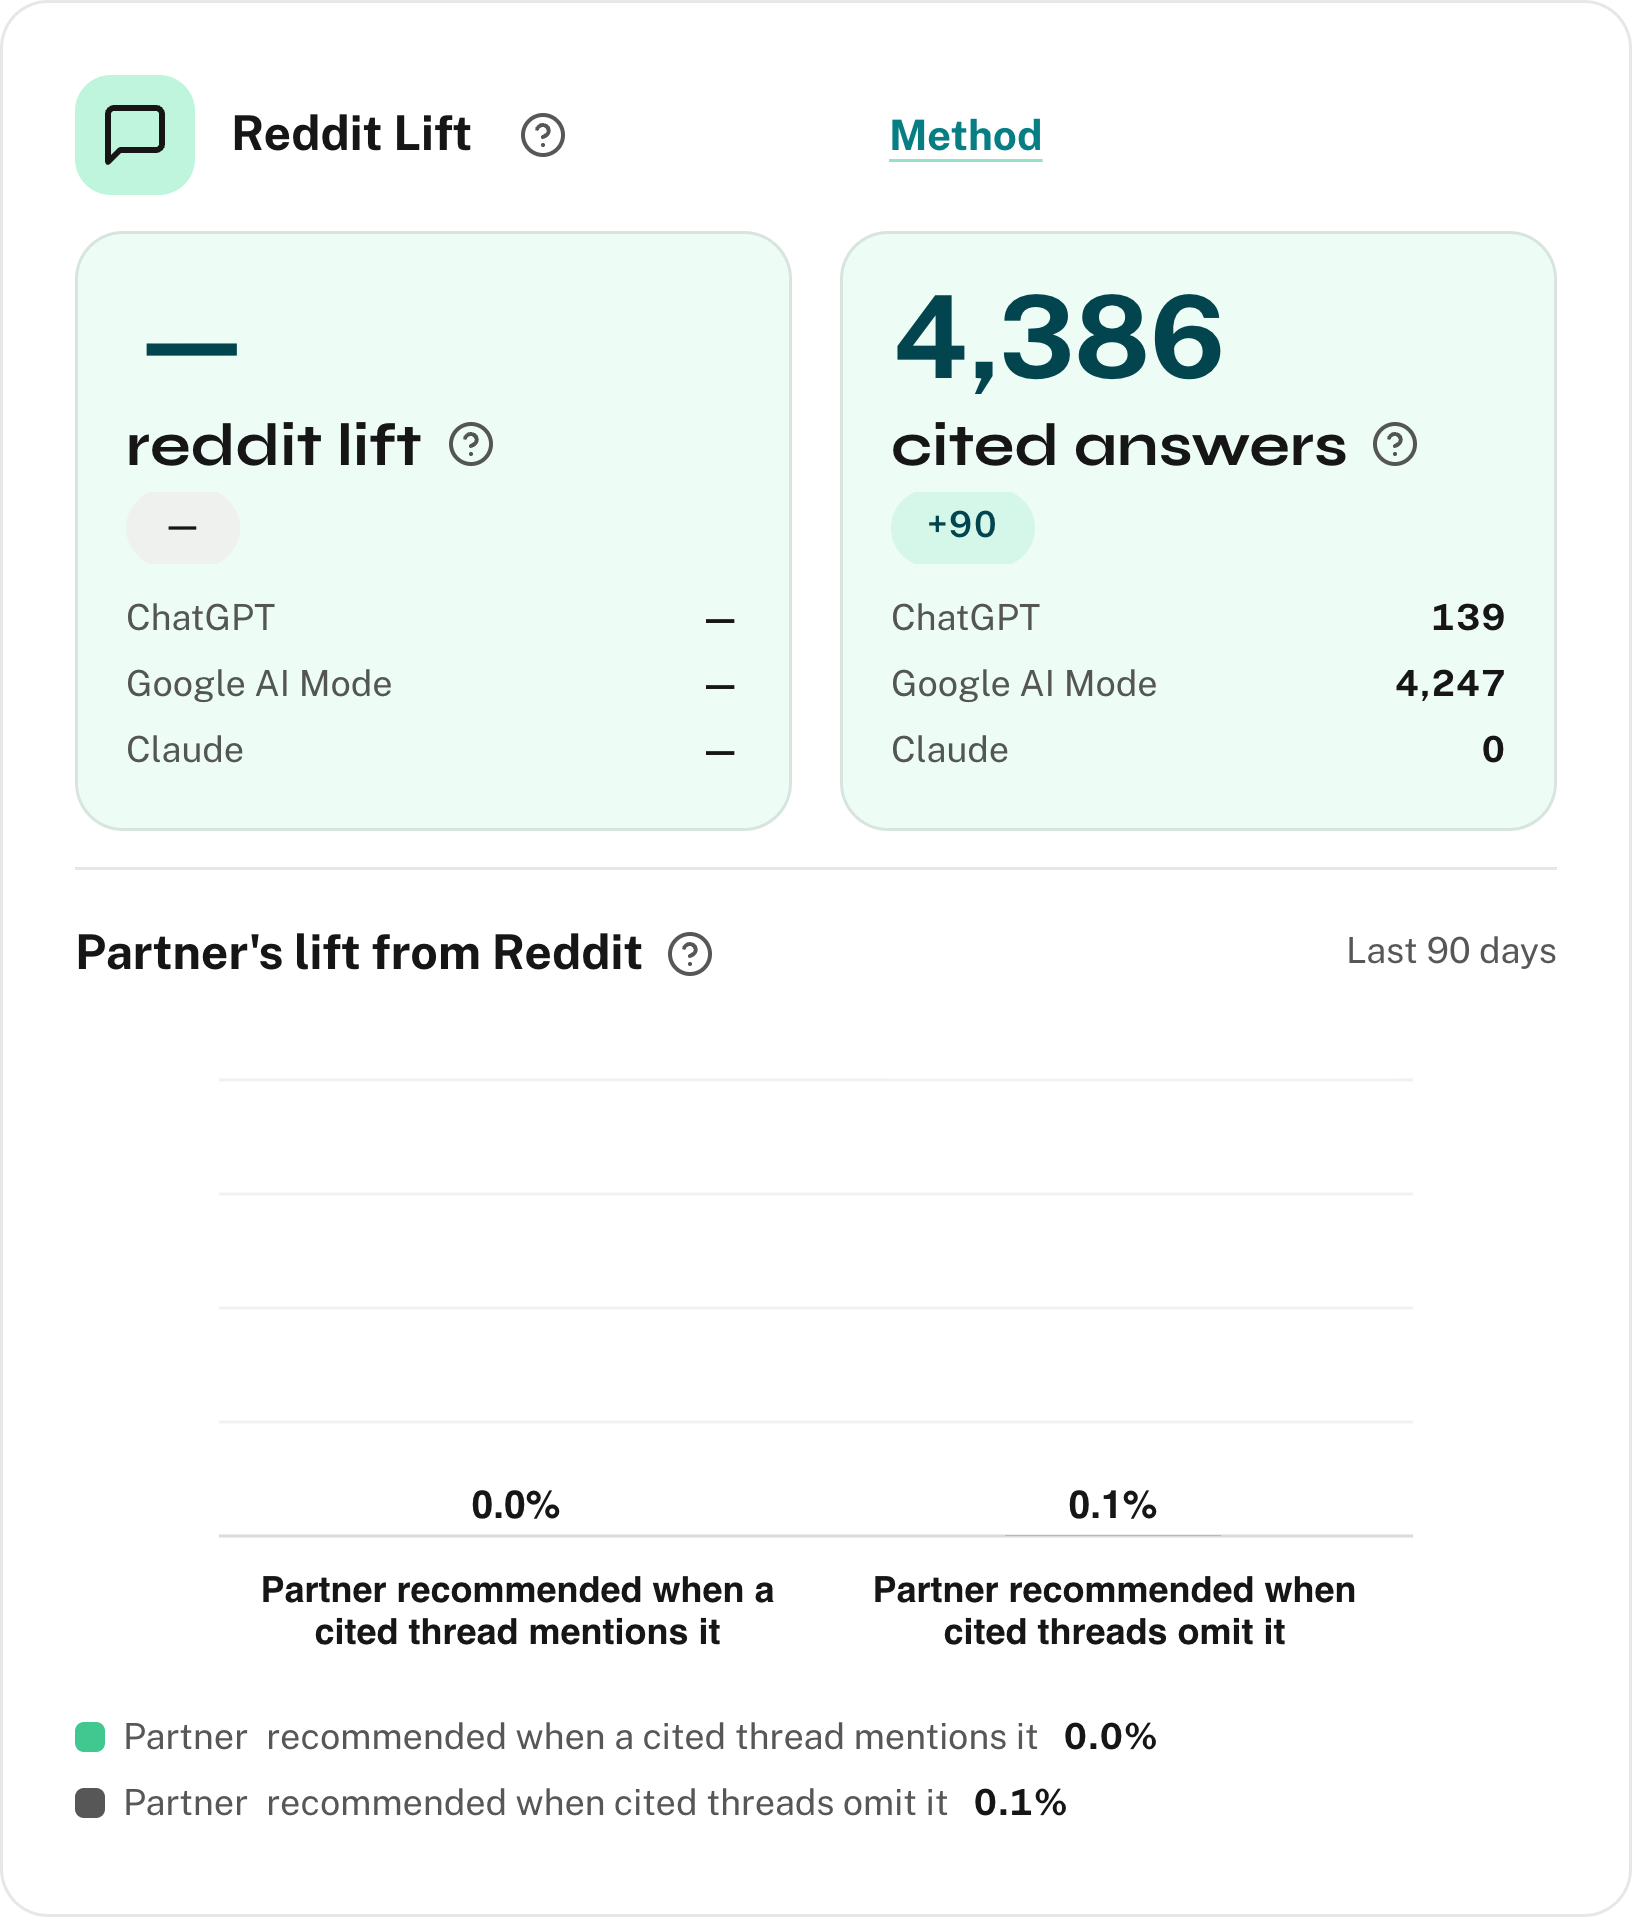
Google AI Mode and ChatGPT are asked the same number of questions here, and Google AI Mode’s count is about thirty times ChatGPT’s. Claude’s count is zero. On their own rows, those counts make the case for aiming Reddit work at Google AI Mode, and a pooled figure would have hidden it.
Our first job on a partner’s plan is splitting the blend and sorting every cited page by kind, because those two readings show which engine the work can reach. Then each engine gets the work its own row calls for:
- A case for your product, sent to the editor of each listicle or comparison page the answers cite, because all three engines read them
- Reddit replies from our team, within each community’s rules, when your buyers mostly ask Google AI Mode, the one engine here that reads Reddit
- A front page that says plainly what you do, because ChatGPT cites companies’ own front pages more than the other two do
- Reports with each engine on its own row, every recommendation carrying its first step
Generative engine optimization (GEO), the work of getting a brand into AI answers, takes months to show momentum. A per-engine reading shows which engine moved first while the blend still looks flat.
Frequently Asked Questions
Which engine deserves a SaaS company’s first quarter of work?
The one your buyers use and your work can reach. Ask new leads which assistant they used on the first call and keep the answer in your CRM. Then read what that engine cites. If it leans on listicles and comparison pages, start there. If it reads Reddit, threads in your buyers’ subreddits come next. Do not start with the lowest number by default, because a low figure can mean the engine reads pages your work cannot reach.
Do we need thousands of questions to read engines separately?
No, but each engine needs enough answers for a real change to clear its own week-to-week range. A smaller set can work if you keep it fixed and wait more weeks before deciding a change is real. The trade-off is time. With fewer questions, one odd answer moves the figure further, so the median of several weeks matters more than any single reading. Cover every product line and buyer role first, then add questions where a reading still swings.
Should every engine get the same number of questions?
Not necessarily, because collection costs differ. What matters is not pooling engines into one figure at all, since unequal counts tilt the blend toward the larger sets. Report each engine on its own row with its own count. If you ask one engine fewer questions, compare it with the others only on the questions they all share. On this panel the shared set was 245 questions, and on them Claude still cited Reddit nowhere while the others did.
Does an answer with no citations mean our brand was invisible?
No. An answer with no sources says nothing about which pages an engine reads, so it is missing data for a source question. It still counts for a naming question, because the buyer read it whether or not it linked anything. Log sourceless answers in their own column and never count them as zeros for a source. If many come back without sources in one week, look into it before reading the figure, since a collection problem and answers from memory look alike.
Why does Claude not cite Reddit?
When we pointed Claude’s web search at Reddit on 28 October, the tool refused the site. On this panel, Claude cited Reddit in none of 1,196 cited answers, even where Google AI Mode cited it often. Claude reads listicles, comparison pages and Wikipedia instead, so a brand reaches it there. Anthropic can change its tool, so repeat a test like ours before you plan a quarter around it. If your buyers use Claude, give its share of the work to listicles.
Should we stop Reddit work because one engine shows zero?
Not if your buyers use an engine that reads Reddit. On this panel Google AI Mode cited Reddit in roughly 13% of its cited answers while Claude never did. The zero tells you Reddit work is unlikely to show up on Claude as it is set up today. That is a reason to aim the Reddit work at Google AI Mode and give Claude’s share of the quarter to listicles. Check the zero again each quarter, because engines change what they read.
How many weeks before a move on one engine is real?
Take at least four weekly readings and compare the median with the range the engine moved in before the work began. Treat a move inside that range as noise until more weeks say otherwise. That is a working rule, and a proper statistical test needs more data. On this panel, Google AI Mode’s Reddit share moved almost three points over four weeks, so a smaller change proves nothing on its own. The fewer questions you track, the more weeks you need.
Can our team read engines separately without a panel?
Yes. A spreadsheet with a row for every answer and the log’s fields will do, filled on the same weekday each week. It gets slow as questions and markets grow, which is when teams automate the asking and saving. Record the surface too, such as an app, a results page or an API, since two readings of one engine through different surfaces can disagree. Whatever does the asking, keep the settings written down so each week’s readings compare with the last.
How do we know our work caused an improvement?
Compare the questions the work touched with the questions it left alone, such as questions whose cited listicles now name you against the rest. Read each engine on both groups, before and after. A rise on the touched group alone is evidence the work helped, though the two groups may differ in other ways. A rise on both groups suggests something outside the work changed, such as the engine itself. Without the split, you could not tell those cases apart.
Can a per-engine report predict leads?
Not by itself. It shows where buyers can see you on each engine, and the sale shows up in your pipeline. Pair it with the first-call answer about which assistant a lead used, and read the two together each quarter. If an engine’s figure rises and leads from that engine rise with it, that is a reason to keep going there, though still an association. If the figure rises and those leads do not, that engine may not be where your buyers decide.
Sources (3)
- Empact Partners, "per-engine run on one partner’s Empact Panel in a B2B software category" (2026)Empact Partners' own data↩1↩2↩3↩441,200 answers to unbranded buyer questions (5,000 questions a week on ChatGPT and on Google AI Mode, 300 on Claude, four weekly waves from 15 October to 5 November 2026), every cited page classed by kind; read 13 November 2026.
- Empact Partners, roundup test on another partner’s Empact Panel: answers citing at least one verified roundup, ChatGPT and Claude, 2 to 23 September 2026, published in, "48 AI Search Citation Statistics" (2026)Empact Partners' own data↩1
- Empact Partners, "test of Claude’s web search tool asked to search reddit.com, 28 October 2026" (2026)Empact Partners' own data↩1
Keep reading
GEO Should You Report Brand Visibility or Share of Voice?
Choose an AI-search metric your board can compare, keep the measurement consistent, and separate brand mentions from buyer choice.
GEO How to Measure AI Search Visibility for Your SaaS Brand
Measure where AI names your SaaS brand, compare rivals fairly, and turn citation gaps into a plan your team owns.
GEO How to Choose Your Next SaaS AI Visibility Fix
Use AI visibility counts and the answers behind them to choose which SaaS pages, mentions or discussions need work.