How to Log What ChatGPT and Claude Search Before They Answer
Log the searches ChatGPT and Claude run through their APIs for your buyer questions, keep the ones that recur, and decide what each needs.
On this page
Empact Newsletter
One email a month on what is working in AI search and SaaS go-to-market.
A marketing team about to pay for pages that AI engines will cite usually decides what to write from the answers it reads. Those answers never show what the engine looked up first. We sent eight buyer questions to ChatGPT and Claude through their APIs, the doors software uses to call a model directly. One was “top GEO consultancies for B2B SaaS”, GEO being generative engine optimization.
Both engines searched nearly those words in all five runs. ChatGPT’s search came back mostly with pages on selling abroad, and Claude’s with the same nine roundups of GEO consultancies every time. The steps below log those searches for your own questions, group them into needs and put a decision beside each one that recurs.
My company, Empact Partners, gets SaaS products into AI answers on Claude, ChatGPT and Google AI Mode, partly by getting them named in the roundups those engines look up. A search log shows which roundups those are, and running one takes five things.
This procedure records what the models search when software calls them, not what buyers see in the ChatGPT app, how often they ask, or anything about Google. DataForSEO’s LLM Responses API, its service for calling large language models (LLMs), does the calling with web search on and returns both engines’ searches in one format 1 2.
Logging the Searches Behind Five Runs of Each Question
Write the Questions File
Create a folder for the run, put your buyer questions in a plain text file one per line, and save it there as questions.txt. Pick questions whose honest answer names companies, worded as a buyer would type them, with no brand name in them. These are the eight we ran, all about one B2B services category:
company that can make our startup show up in ChatGPT recommendations
top GEO consultancies for B2B SaaS
affordable AI search consultancy for startups
AI search consultancy for scaling from Series A to Series B
company that builds mentions and UGC so AI engines recommend our software
our SaaS never comes up in ChatGPT, which company can change that?
company that helps B2B brands get featured in AI Overviews
consultancy to get our product recommended when people ask AI for the best tools
Leave the file alone once the first call is bought. The script files each response under its question’s line number, so an edited line would inherit the old line’s answers. For new questions, start a new folder.
Save the Script and Run It
Everything from here happens in the run folder, in one terminal window, in this order:
From the script to the last call
Save the script.
Save the file below as
log_searches.py. Other models go inENGINES, another country inask().Paste the API login.
DataForSEO’s API Access page shows an API login and password, separate from your sign-in.
Run the pilot.
It asks question 1 once on each engine before anything else is spent.
Read the pilot’s lines.
Each call prints how many searches it ran, its citation marks and its cost. A
Refused: HTTP 401line means a wrong login.Run all five rounds with a budget.
The pilot’s two calls are reused and the other 78 bought.
Rerun the same command after a refusal.
It resumes at the call that failed. After a
not re-sentline, check your balance first.
The script, exactly as it ran on 30 October 2026 and produced every number from that run on this page 8:
#!/usr/bin/env python3
"""Send buyer questions to ChatGPT and Claude through DataForSEO's LLM Responses API,
log every web search each model ran before answering, and rank the searches that recur.

  export DATAFORSEO_LOGIN=...  DATAFORSEO_PASSWORD=...
  python3 log_searches.py --pilot           # question 1, once on each engine
  python3 log_searches.py --repeats 5       # the full run; calls already bought are reused

Writes raw/ (every response), runs.csv (one row per call), searches.csv (one row per
search) and ranked.csv (each search, and in how many runs each engine made it).
"""
import argparse, base64, csv, json, os, re, urllib.error, urllib.request
from pathlib import Path

ENGINES = {  # engine: (DataForSEO path segment, model)
    "chatgpt": ("chat_gpt", "gpt-4.1-mini"),
    "claude": ("claude", "claude-haiku-4-5"),
}
API = "https://api.dataforseo.com/v3/ai_optimization/{}/llm_responses/live"


def ask(segment, model, question, auth):
    body = [{"user_prompt": question, "model_name": model, "web_search": True,
             "web_search_country_iso_code": "US", "max_output_tokens": 300}]
    req = urllib.request.Request(API.format(segment), data=json.dumps(body).encode(),
                                 headers={"Authorization": "Basic " + auth,
                                          "Content-Type": "application/json"})
    with urllib.request.urlopen(req, timeout=180) as r:
        return json.load(r)


def find(obj, key):
    """Every value stored under `key`, anywhere in the response."""
    if isinstance(obj, dict):
        for k, v in obj.items():
            if k == key:
                yield v
            yield from find(v, key)
    elif isinstance(obj, list):
        for v in obj:
            yield from find(v, key)


def read(resp):
    task = resp["tasks"][0]
    result = (task.get("result") or [{}])[0]
    flat = lambda key: [x for v in find(result, key) if v for x in v]
    return {"status": task["status_code"], "cost": task.get("cost") or 0,
            "money_spent": result.get("money_spent") or 0,
            "web_search": result.get("web_search"), "searches": flat("fan_out_queries"),
            "pages": len(flat("search_results")), "cited": len(flat("annotations"))}


def norm(s):
    return re.sub(r"\s+", " ", re.sub(r"[^\w\s]", " ", s.lower())).strip()


def main():
    p = argparse.ArgumentParser()
    p.add_argument("--questions", default="questions.txt")
    p.add_argument("--repeats", type=int, default=5)
    p.add_argument("--pilot", action="store_true", help="question 1, once per engine")
    p.add_argument("--budget", type=float, default=3.00, help="never pass this, in USD")
    a = p.parse_args()

    login, password = os.environ["DATAFORSEO_LOGIN"], os.environ["DATAFORSEO_PASSWORD"]
    auth = base64.b64encode(f"{login}:{password}".encode()).decode()
    questions = [l.strip() for l in open(a.questions) if l.strip() and not l.startswith("#")]
    questions, repeats = (questions[:1], 1) if a.pilot else (questions, a.repeats)
    Path("raw").mkdir(exist_ok=True)

    rows, costs, spent, lost = [], [], 0.0, 0
    for qi, question in enumerate(questions, 1):
        for run in range(1, repeats + 1):
            for engine, (segment, model) in ENGINES.items():
                f = Path(f"raw/{engine}-q{qi:02d}-r{run}.json")
                if f.exists():  # bought already: read it, never pay twice
                    got = read(json.loads(f.read_text()))
                else:
                    nxt = max(costs) if costs else 0.10
                    if spent + nxt > a.budget:
                        print(f"Stopping before ${a.budget:.2f}: the next call could pass it.")
                        return finish(rows, spent, lost)
                    try:
                        resp = ask(segment, model, question, auth)
                    except urllib.error.HTTPError as e:  # refused, so not charged
                        print(f"Refused: HTTP {e.code} {e.read()[:200]!r}")
                        return finish(rows, spent, lost)
                    except Exception as e:  # may have been charged: never re-send it
                        print(f"q{qi} run {run} {engine}: no answer ({e}), not re-sent")
                        spent, lost = spent + nxt, lost + 1
                        continue
                    f.write_text(json.dumps(resp, indent=1))
                    got = read(resp)
                spent += got["cost"]
                costs.append(got["cost"])
                rows.append({"question_no": qi, "question": question, "run": run,
                             "engine": engine, "model": model, **got})
                print(f"q{qi} run {run} {engine:7}  searches {len(got['searches'])}  "
                      f"cited {got['cited']:2}  ${got['cost']:.4f}  total ${spent:.4f}")
    finish(rows, spent, lost)


def finish(rows, spent, lost):
    with open("runs.csv", "w", newline="") as fh:
        w = csv.writer(fh)
        w.writerow(["question_no", "question", "run", "engine", "model", "status", "web_search",
                    "searches", "pages", "cited", "cost_usd", "money_spent_usd"])
        for r in rows:
            w.writerow([r["question_no"], r["question"], r["run"], r["engine"], r["model"],
                        r["status"], r["web_search"], len(r["searches"]), r["pages"],
                        r["cited"], r["cost"], r["money_spent"]])
    with open("searches.csv", "w", newline="") as fh:
        w = csv.writer(fh)
        w.writerow(["question_no", "question", "run", "engine", "search"])
        for r in rows:
            for s in r["searches"]:
                w.writerow([r["question_no"], r["question"], r["run"], r["engine"], s])

    runs, seen, wording = {}, {}, {}
    for r in rows:
        runs.setdefault((r["question_no"], r["engine"]), set()).add(r["run"])
        for s in r["searches"]:
            key = (r["question_no"], norm(s))
            seen.setdefault(key, {}).setdefault(r["engine"], set()).add(r["run"])
            wording.setdefault(key, s)
    ranked = []
    for key, by in seen.items():
        qno = key[0]
        question = next(r["question"] for r in rows if r["question_no"] == qno)
        gpt, cl = len(by.get("chatgpt", ())), len(by.get("claude", ()))
        ranked.append([qno, question, wording[key], gpt, len(runs.get((qno, "chatgpt"), ())),
                       cl, len(runs.get((qno, "claude"), ())), gpt + cl])
    ranked.sort(key=lambda x: (x[0], -x[7], x[2]))
    with open("ranked.csv", "w", newline="") as fh:
        w = csv.writer(fh)
        w.writerow(["question_no", "question", "search", "chatgpt_runs", "chatgpt_of",
                    "claude_runs", "claude_of", "runs_total"])
        w.writerows(ranked)

    for qno in sorted({x[0] for x in ranked}):
        top = [x for x in ranked if x[0] == qno][:3]
        print(f"\nq{qno} {top[0][1]}")
        for x in top:
            print(f"  ChatGPT {x[3]}/{x[4]}  Claude {x[5]}/{x[6]}  {x[2][:64]}")
    print(f"\n{len(rows)} calls, {sum(len(r['searches']) for r in rows)} searches logged, "
          f"{sum(1 for x in ranked if x[7] > 1)} came back in more than one run"
          + (f", {lost} unanswered" if lost else "") + ".")
    print(f"Cost of the calls in this folder: ${spent:.4f}")


if __name__ == "__main__":
    main()
It asks each question with web search allowed but not forced, so whether a model searched at all is part of the record. Each response is saved in raw, and a saved call is read back rather than bought again. Before each new call it estimates the price from the dearest call so far. It stops if that estimate would pass --budget, so the budget is a stopping line with a small margin, not a hard cap.
The login, with your own values between the quotes, then the pilot:
export DATAFORSEO_LOGIN="your API login"
export DATAFORSEO_PASSWORD="your API password"python3 log_searches.py --pilotOurs printed this:
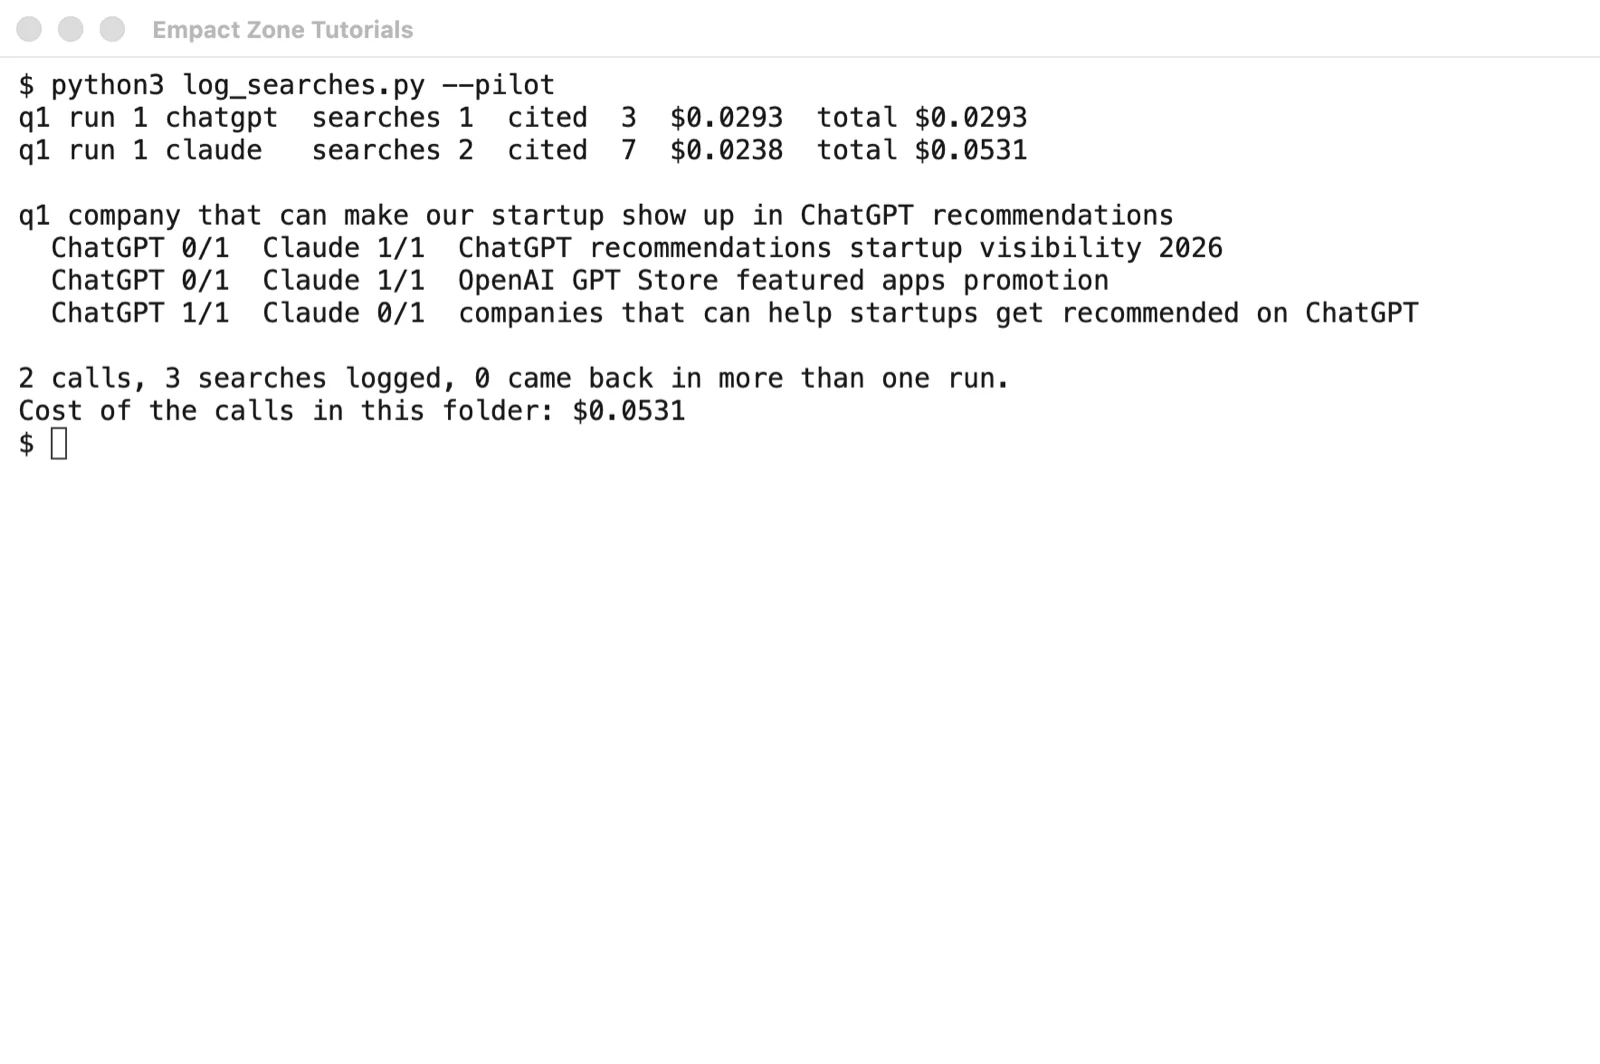
Both engines returned the searches they ran, word for word. For the pages a search returned, ChatGPT gave only the address and Claude the address, title and date 1 2. cited counts citation marks, not pages: Claude marks every cited sentence, so a page cited three times counts three.
The pilot also showed the first misreading. ChatGPT searched question 1 nearly as written, while Claude searched for promotion in OpenAI’s GPT Store, which is where an app gets published, not how a company gets recommended. Then the full run, budget in dollars:
python3 log_searches.py --repeats 5 --budget 2.85Our ceiling was $3, so we passed 2.85 to leave room for a call dearer than the estimate. The run took nineteen minutes, and twenty-three Claude calls came back Refused: HTTP 500, DataForSEO’s code for an error on its own server 3.
Each of those replies said it cost nothing, and our balance fell by exactly the total the script printed, so we reran the command, twenty-four times in all.
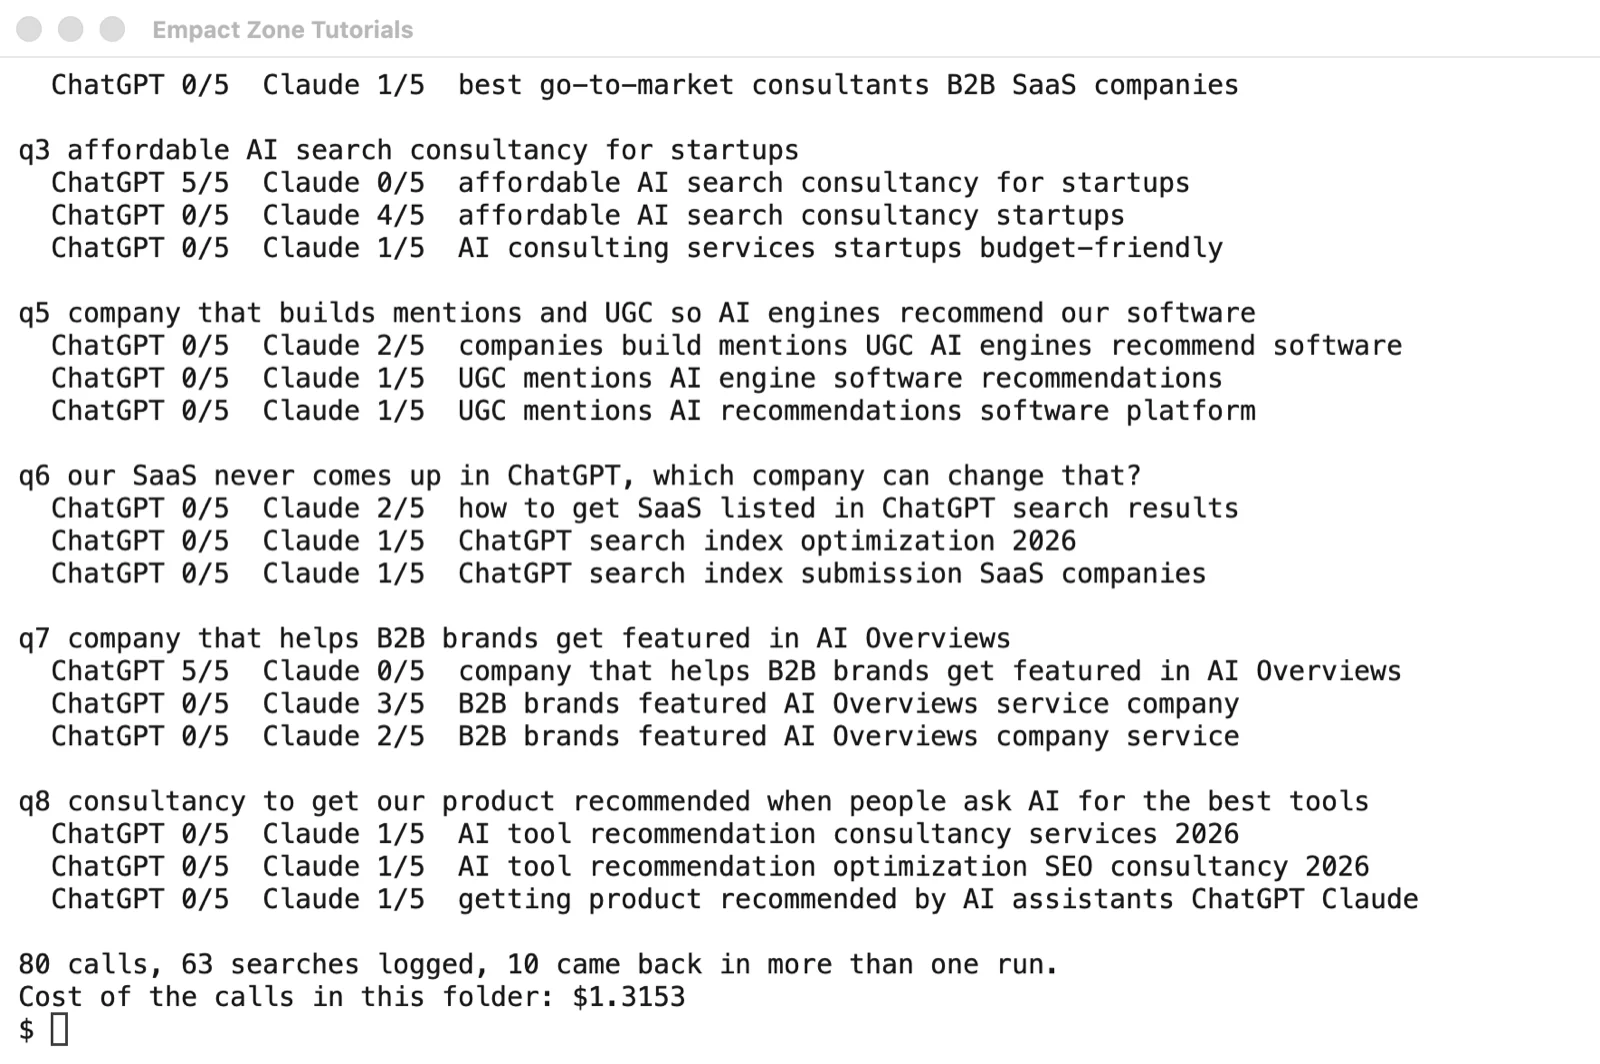
The script treats any HTTP error as a refusal, so after any other code, check your balance before rerunning. A line ending in not re-sent means that call may have been charged, yet nothing was saved, so a rerun buys it again and the new run’s budget misses the first charge. Our last run ended like this:
What to Do With the Searches That Recur
The folder now holds all 63 searches the two models ran, in 38 different wordings, ready to be sorted, grouped by meaning and decided on.
Read ranked.csv
Open ranked.csv, a spreadsheet file, in Google Sheets or Excel and sort by runs_total, largest first. Each row is one search for one question, with case and punctuation ignored. Its columns give the runs out of five in which each engine ran it, and searches.csv keeps every original wording. The rows that rise to the top are the ones this page calls recurring.
Then read across the questions:
Scroll horizontally to see all columns when the table is wider than this page.
| Question | Runs of 5 that searched, ChatGPT / Claude | What the searches show |
|---|---|---|
| 1. Show up in ChatGPT recommendations | 5 / 5 | Claude also searched the GPT Store |
| 2. Top GEO consultancies for B2B SaaS | 5 / 5 | ChatGPT answered about entering new countries |
| 3. Affordable AI search consultancy | 5 / 4 | Claude drifted into AI consulting in three runs |
| 4. Series A to Series B | 0 / 0 | ChatGPT advised, and Claude asked what we meant |
| 5. Mentions and UGC | 0 / 5 | Claude found AI video tools for user-generated content |
| 6. Never comes up in ChatGPT | 0 / 2 | Claude searched for ChatGPT’s search index |
| 7. Featured in AI Overviews | 5 / 5 | Both read it as asked |
| 8. Recommended for best tools | 0 / 2 | Three wordings, none twice |
ChatGPT searched the buyer’s words as typed in 15 of its 20 searches, while Claude rewrote all 43 of its own, so read each engine’s rows on their own.
In all five runs both engines searched for the top GEO consultancies for B2B SaaS, and only Claude came back with roundups of them. ChatGPT came back mostly with pages on growing into new countries.
Group the Wordings by Meaning
Exact text undercounts. ChatGPT’s five searches for question 1 are five slightly different sentences, so the sheet shows each as a one-off, when all five ask for the same companies, once in every run. In the run folder, type claude to open Claude Code and paste this prompt:
Read ranked.csv in this folder. Each row is a web search that ChatGPT or Claude ran before answering one of our buyer questions, with the number of runs (out of five) in which each engine ran it.

1. Group the searches that ask for the same thing in different words, within each question. Keep every original wording in its group.
2. For each group, count the runs on each engine. A run counts once per engine even if several wordings of the group appeared in it; use searches.csv to check.
3. Mark a group "recurring" if it came back in 3 or more of 5 runs on either engine, "occasional" at 2, and "one-off" at 1.
4. For each recurring or occasional group, write in one line the page a buyer would need to find for that search, and say what kind of page it is: listicle, comparison, how-to, pricing, or definition.
5. Write content-needs.csv with the columns question_no, group, wordings, chatgpt_runs, claude_runs, status, page_needed, page_type. Sort it by question_no, then recurring first.

Use only the searches in the files. Do not add searches, and do not merge groups across questions.
Ours turned 38 wordings into 14 needs, 8 of them recurring, and wrote content-needs.csv. The table in the next step covers all 8. The four that ask for company names share a row, and the GEO need gets a row for each engine. We ran the prompt once, on Sonnet, and checked every row against searches.csv. The grouping is a model’s judgment, and a wrong merge would point a page at a need nobody searched for.
Decide What Each Need Gets
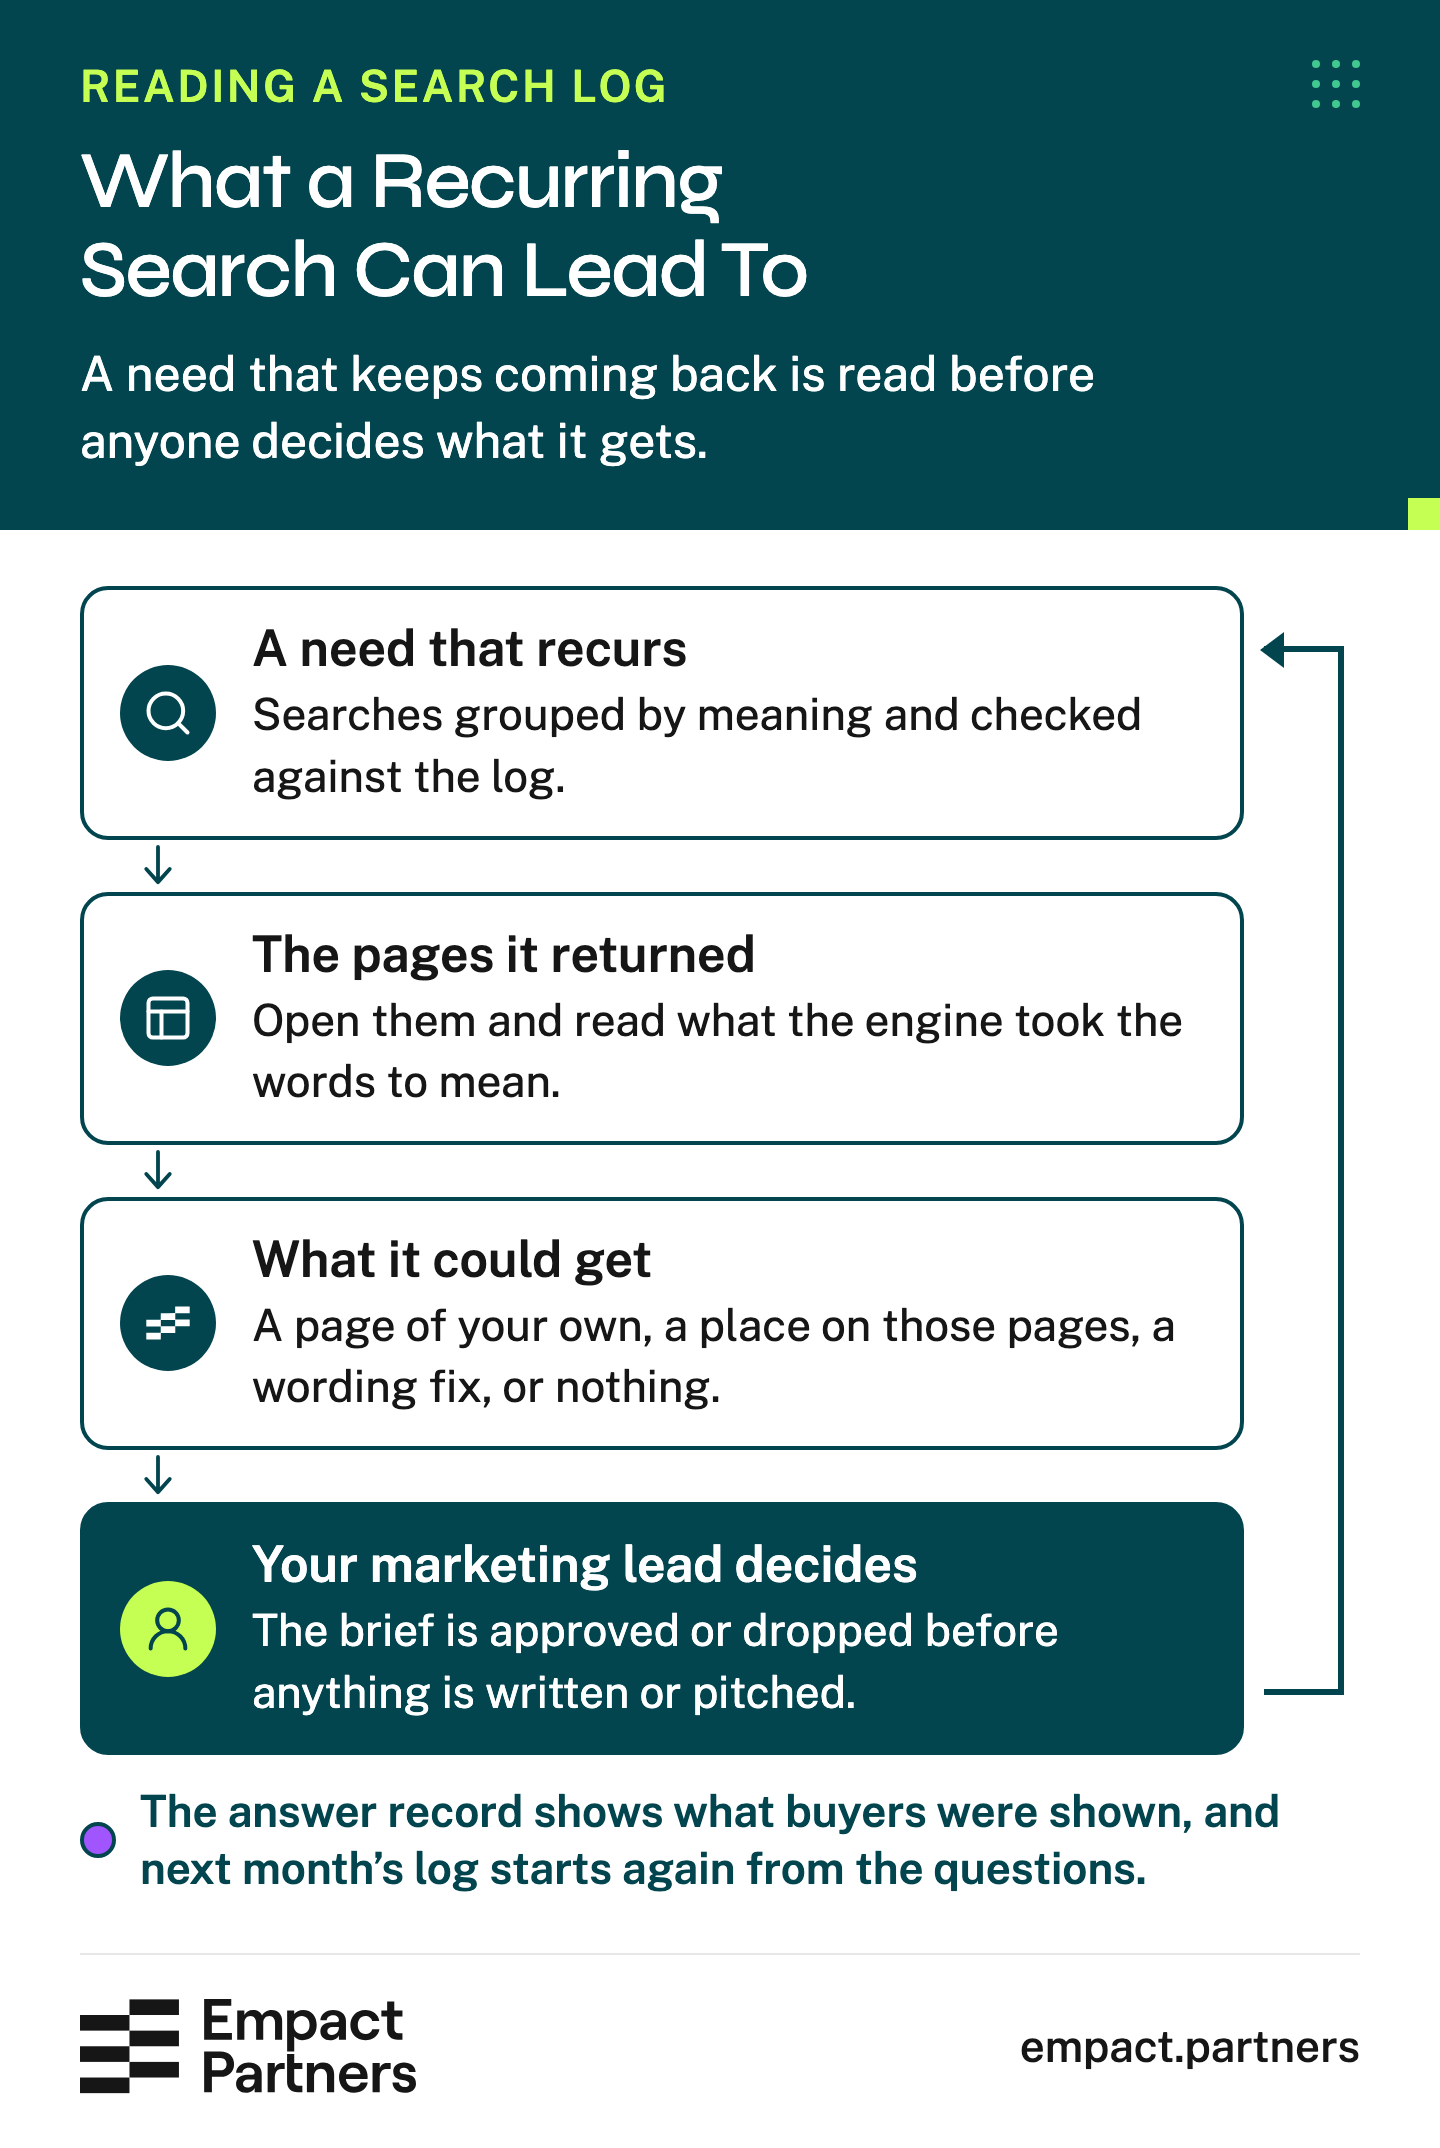
A recurring need can get one of four answers: a page of your own, a place on the pages its searches returned, a fix to the words on your site, or nothing. The file cannot choose, because it cannot see your site, your prices or which of those pages you could join. Your marketing lead decides, after someone opens the pages each search returned. In our run, the eight needs got these answers:
Scroll horizontally to see all columns when the table is wider than this page.
| Recurring need (engine, runs of 5) | What it gets | Why |
|---|---|---|
| How a startup gets recommended in ChatGPT (Claude, 5) | A guide of your own, in the searched words | It asks how, which a roundup of vendors does not answer |
| Top GEO consultancies for B2B SaaS (Claude, 5) | A place on the nine roundups it returned | The same nine came back in all five runs |
| Top GEO consultancies for B2B SaaS (ChatGPT, 5) | A wording test: generative engine optimization spelled out beside GEO | ChatGPT’s search read GEO as geography |
| Company roundups for questions 1, 3, 5 and 7 (ChatGPT 5, or Claude 3 to 5) | A place on the roundups returned, once someone has opened them | Each asks for names, so a roundup is the answer |
| Getting into the GPT Store (Claude, 5) | Nothing | It asks how to publish an app there |
| Cheap AI consulting for early-stage companies (Claude, 3) | A page only where you publish prices | It asks for price |
| Question 4, never searched | Nothing from this log | No call searched, so watch the answer record |
Every row went through the same reading before it got an answer:
The GPT Store need shows why a high count alone never earns a page:
Read what a search means before you commission a page for it. The GPT Store search came back in all five of Claude’s runs and still answered a question no marketing team was asking. Recurrence tells you where to look first. The pages behind the search tell you whether to act.
 Vlad Shvets on LinkedInOpens in a new tab
Run five checks on every row:
Before a recurring need gets a page or a pitch
- The grouping matches
searches.csvrow for row - The need came back in at least three of five runs on one engine
- Someone has read what the search means, not only its words
- Someone opened the pages it returned
- One named person owns the decision
The fourth check, opening the pages a search returned, takes longest when they are roundups of your rivals, and a free tool can do the first pass. Given your website, the AI Citation Gap Report below emails you the cited pages that mention your rivals but not you, grouped by kind, each with its way in. It is a free preview of an agent we run, and the full agent runs for our partners.
How the API Log Differs From the ChatGPT App
Everything so far came from the API, but buyers ask in the ChatGPT app, so we checked how much the two agree. The Empact Panel is a tool we built that puts a partner’s buyer questions to ChatGPT, Google AI Mode and Claude every week and stores each answer together with the pages cited. We run it on our own category too, which is where the eight questions came from.
In four weekly readings from 4 to 23 October, the Panel saw the ChatGPT app cite 148 sites for them, counting a site once per question 9. Three were among the pages the ChatGPT API’s searches returned in our run, and ten among either engine’s. The records also differ in model, dates and measure: the app ran a newer model earlier in the month, and counts cited sites where the log counts returned pages. They show the overlap, not why it is small.
DataForSEO draws the same line: its scraper reads answers as users see them, while this API is for studying how models generate answers 4. Nor can a search log show whether being named on a roundup changes the answer. The Panel’s weekly record can: it counts how often answers recommend a company when a cited listicle names it, and when none does. On one partner’s panel, compare the two bars:
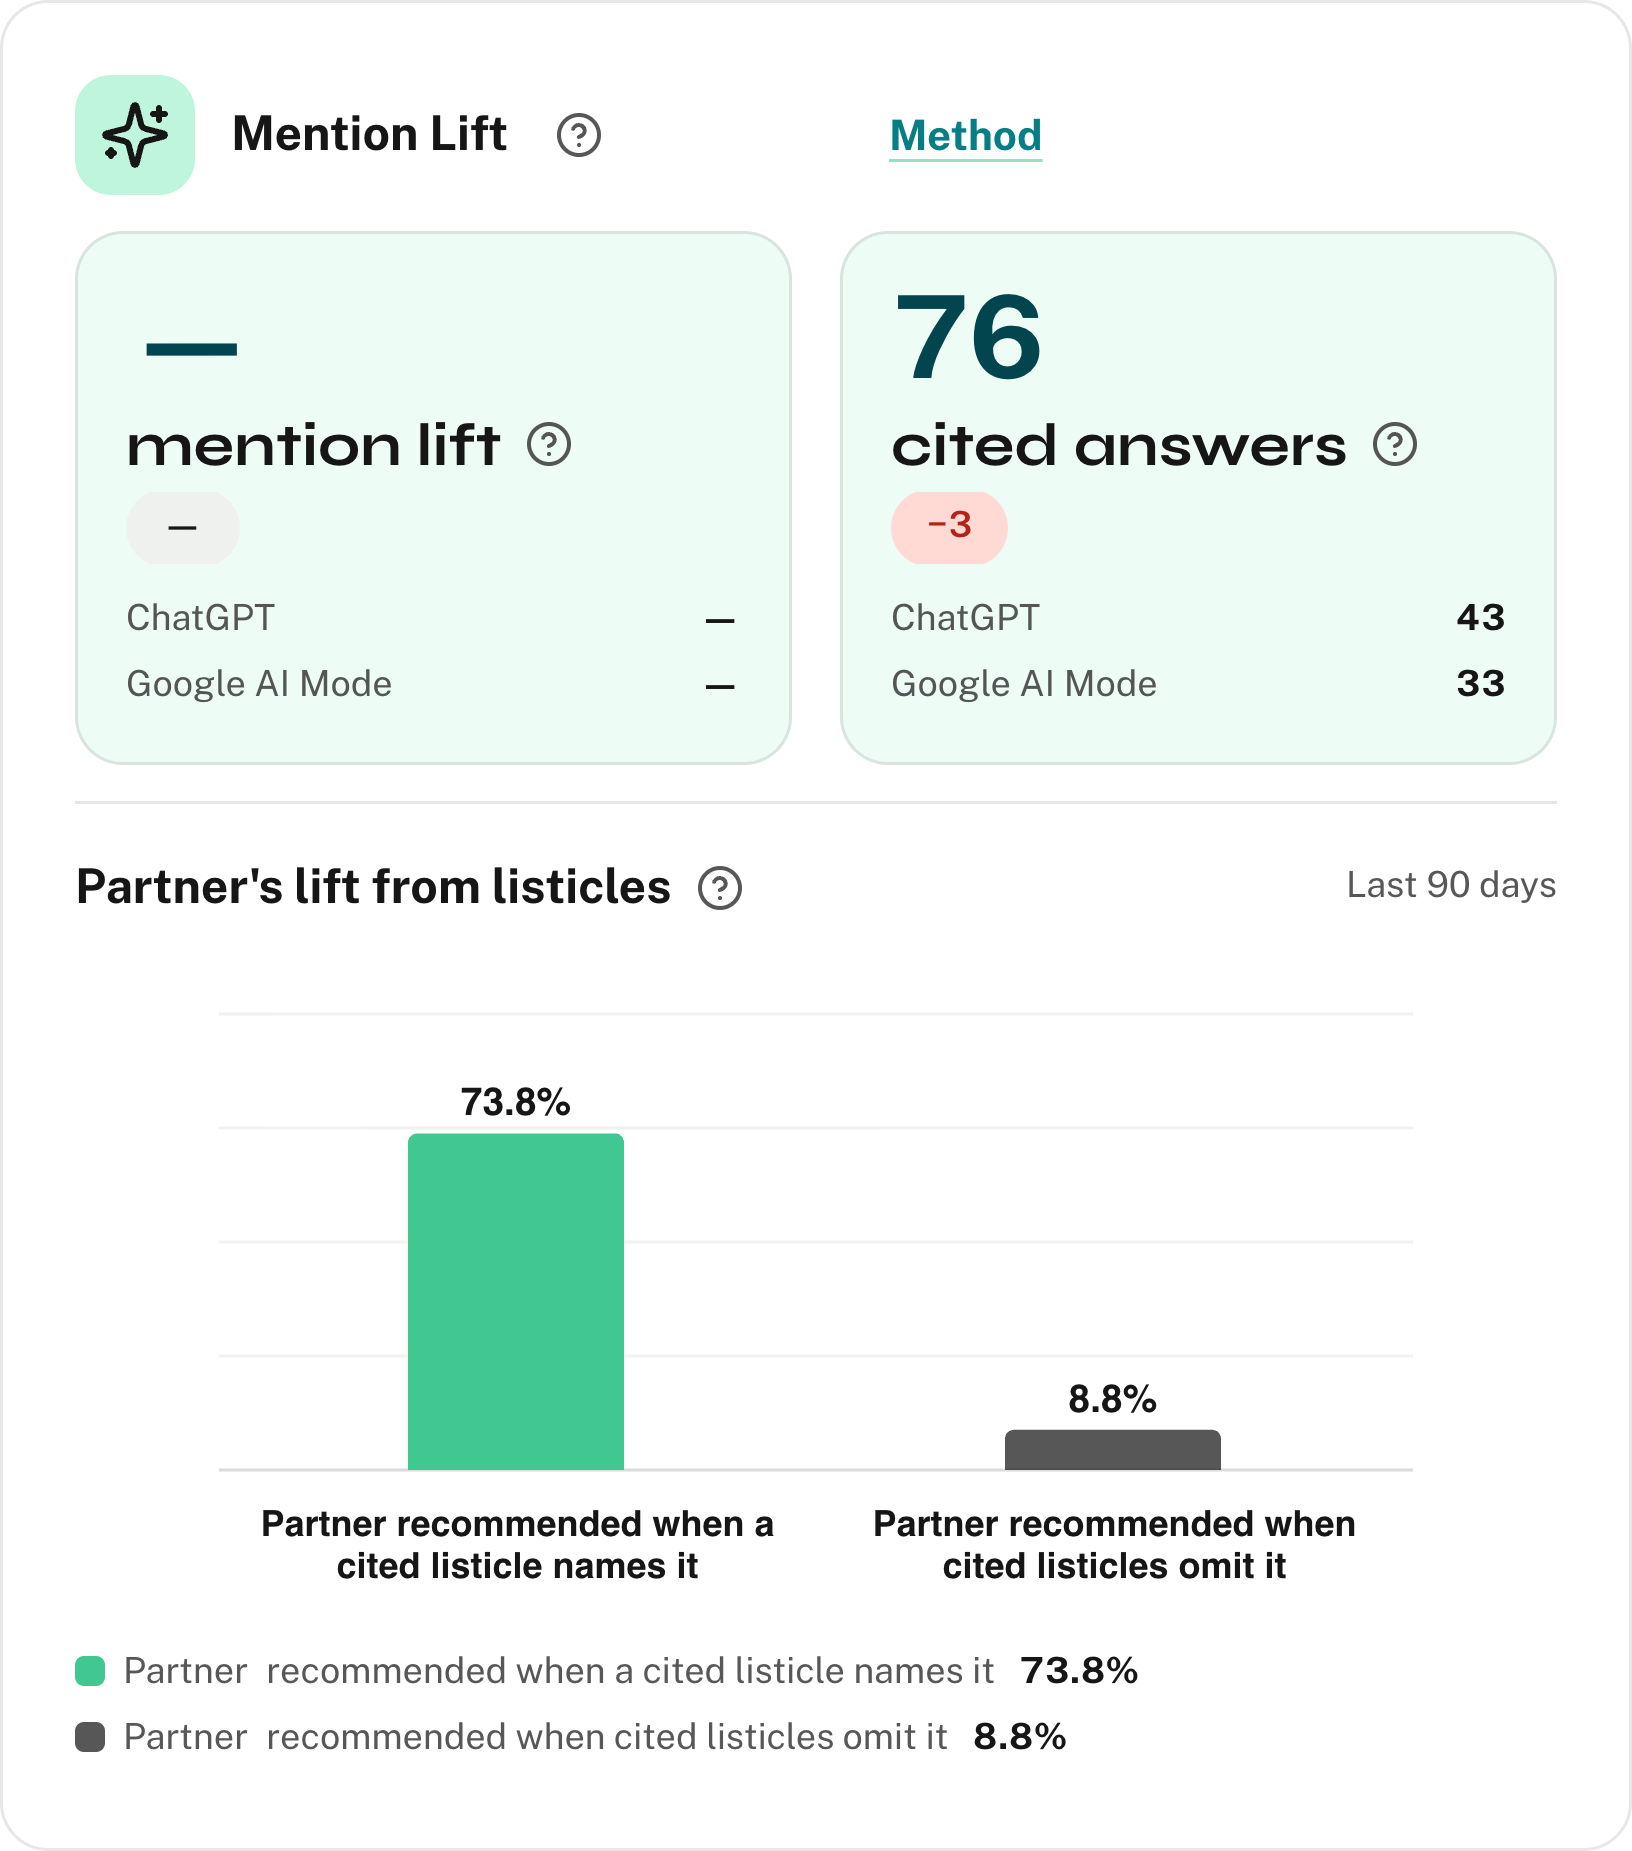
Over the card’s 90 days, answers recommended the partner more than eight times as often when a cited listicle named it, on a small base of 76 cited answers. That is the reading to take for your own category before a month of outreach on the roundups your log turned up.
If your team would rather work those roundups itself, the playbook below, How to Win the Pages AI Engines Cite for Your Category, shows how to get onto them, starting where you are missing.
Rerun the Log Next Month
Rerun the log in a month with the same questions.txt in a new folder, so last month’s answers stay put. Then check whether your own domain came back among the returned pages: put it in place of yourcompany.com and run this in the new folder.
python3 - yourcompany.com <<'EOF'
import json, sys
from pathlib import Path
from urllib.parse import urlsplit

domain = sys.argv[1].lower().removeprefix("www.")
for f in sorted(Path("raw").glob("*.json")):
    result = (json.loads(f.read_text())["tasks"][0].get("result") or [{}])[0]
    hosts = {(urlsplit(p["url"]).hostname or "").removeprefix("www.")
             for p in result.get("search_results") or []}
    if any(h == domain or h.endswith("." + domain) for h in hosts):
        print(f.name)
EOF
It reads only the search_results field, so a domain named in an answer but never returned by a search prints nothing, where a text search of the files would count both. A printed file name means your page came back in that call’s search, not that an answer named you.
In our log, the first check next month is whether the nine roundups behind Claude’s GEO search come back. In yours, it is the roundups behind your own recurring needs. A roundup that comes back in two monthly logs earns outreach time more surely than one run can, and one that drops out tells you so before you pitch anyone.
When we run this log for a SaaS company, we start with the needs that came back in every run, because those are the most likely to repay a page or a placement. We open the pages behind each one, write the missing page with your experts and pitch each roundup’s editor with a case for your product. You get a decision on every recurring need, and each week we compare every placement we win with the answers your buyers get:
What a search log with us covers
- Your own buyer questions, run the way this page runs them
- Every grouping checked and every returned page read before a decision
- A page written with your experts where those pages leave a gap, through our content marketing
- A pitch to the editor of each roundup worth joining, through mention building
- Each placement compared weekly with what Claude, ChatGPT and Google AI Mode tell buyers
Frequently Asked Questions
Do the API searches show what our buyers see in the ChatGPT app?
No. Buyers use the app, and in our comparison the app ran a different model, on different dates, on a different surface from the one this script calls. For the same eight questions, only 3 of the 148 sites the app cited were among the pages the ChatGPT API’s searches returned. Use the log to learn what an engine looks up, keep a weekly answer record for what buyers are shown, and check every page the log points at against that record.
What does a run like this cost, and what else should we budget?
Ours cost $1.32 for 80 calls, which covered eight questions, five runs on each engine and the pilot. The price moves with the models you choose and the length of their answers, because each call bills the model’s own price plus a small fee per task 4. The minimum top-up means you put down more than the run costs 5. The bigger cost is reading: plan on an hour of a marketer’s time per run, and longer the first time.
Are five runs of each question enough?
Enough to decide what to read first, not enough for a confidence figure. Five runs are enough to tell a search that keeps coming back from one that turned up once. If a need sits at two of five, run the same folder again with --repeats 10, which keeps the five calls you bought and adds five more. Then change “out of five” and the three-run cut in the grouping prompt to “out of ten” and six runs, so the share stays the same.
Why did ChatGPT and Claude search so differently for the same questions?
In this run ChatGPT searched every time on four questions and never on the other four, mostly in the buyer’s own words. Claude searched on seven of the eight, not in every run, and rewrote each search. The two also got different pages back for nearly identical words, which points to different search systems behind them. Keep their counts apart, because a need that recurs on one engine alone is a finding, not noise.
What does it mean when an engine runs no search?
Those calls answered from what the model already held. On question 4, ChatGPT gave general advice and Claude asked what kind of company we were, in all ten calls. That describes those calls on that day, not what either engine will do next month. Keep the question in next month’s file to see whether searching starts, and watch the answer record for whether anyone gets named meanwhile.
Should we write a new page for every recurring search?
No. In our run most recurring needs called for something else: one for a place on existing roundups, one for a wording test, one for nothing. Open the pages a search returned before deciding. If they are roundups of companies, the work is getting onto them. If they are guides nobody in your category has written well, that gap is where a page earns its cost.
Would our own OpenAI and Anthropic API keys work instead of DataForSEO?
Both vendors document a record of the searches their models run. OpenAI says its web search record “will usually (but not always)” include the queries 6, and Anthropic returns each query Claude ran in its response 7. We have not run that route, so we make no claim about its results or its cost. The questions file and every reading step would stay the same, while the script’s calls and field names would change.
How often should we rerun the log?
Monthly, with the same questions file in a fresh folder, comparing which needs recur and which pages come back for them. The answers buyers see move faster, so the answer record runs weekly beside it. Rerun sooner after you publish a page, since that is the first moment the domain check can show your site among the returned pages. After you land on a roundup, check whether that roundup’s page comes back.
Can we run the log for another country or language?
Yes. Change "US" in the script’s ask() to the country code you want. DataForSEO publishes the codes it accepts for each engine 2. Write that market’s questions in the language its buyers use. Give each market its own folder, because the script counts runs per question number and would mix two markets’ answers in one.
Does a recurring search prove that buyers ask that question?
No. It shows the model kept running that search for the question you sent. It says nothing about how often buyers send that question in the first place. Choose questions from what buyers really ask, in sales calls, demo requests and support tickets, and use the log to learn what each engine does with them. Keyword tools measure Google demand, which is a separate thing again.
Who on our team should own what the log turns up?
Whoever owns the content plan, usually the head of marketing. Each answer turns on things only the company knows: whether it publishes prices, which roundups it could realistically join, and what its pages already say. Give one person the final say on every recurring need, because a log nobody owns becomes a spreadsheet of interesting searches and changes nothing.
Sources (9)
- DataForSEO, "Live ChatGPT LLM Responses" (2026)↩1↩2API documentation, 2026.
- DataForSEO, "Live Claude LLM Responses" (2026)↩1↩2↩3API documentation, 2026.
- DataForSEO, "Errors" (2026)↩1API documentation, 2026.
- DataForSEO, "LLM Responses API pricing" (2026)↩1↩2pricing page and FAQ, 2026.
- DataForSEO, "Pricing" (2026)↩1minimum top-up, 2026.
- OpenAI, "Web search" (2026)↩1API documentation, 2026.
- Anthropic, "Web search tool" (2026)↩1Claude Platform documentation, 2026.
- Empact Partners, "the 30 October 2026" (2026)Empact Partners' own data↩1run: the script, its 80 saved responses, runs.csv, searches.csv, ranked.csv, content-needs.csv and the DataForSEO balance before and after, read again on 13 November 2026.
- Empact Panel, "the ChatGPT app’s answers to the same eight questions, four weekly readings from 4 to 23 October 2026" (2026)Empact Partners' own data↩1compared with the run’s returned pages on 13 November 2026.
Keep reading
GEO How to Write a Buyer Question Set for AI Visibility Tracking
Your AI visibility number is only as honest as its questions. Draft them in Claude from your own pages, then cut the ones that flatter you.
GEO What Your Team Needs Instead of Another AI Search Course
Your team has read the AI search guides. What it lacks is one owner for outreach to the pages AI answers cite, and fixed questions.
GEO Should You Report Brand Visibility or Share of Voice?
Choose an AI-search metric your board can compare, keep the measurement consistent, and separate brand mentions from buyer choice.