


The slide last month said the brand showed up in two answers out of five. The slide for the Thursday readout says one in eight. Nobody touched the website, nothing shipped, no competitor launched anything, and the only honest sentence available right now is that the number moved.
Two days is not enough time to rebuild a measurement program. It is enough time to work out whether the first number was ever worth reporting, which is a different and more useful question.
Nobody Publishes The Number You Are Reporting
Start with the part the dashboards do not say out loud. No engine reports how often it names your brand. There is no ChatGPT equivalent of an impressions column, and there is no feed to subscribe to.
The sharpest version of this turned up in r/SEO in September, in the top comment on a thread from somebody asking the same question:
“no one can tell you how much you show up in ChatGPT, for example, since they don’t publish any statistics. the tools are guessing for the sole purpose of charging people money.” — u/VillageHomeF, r/SEO, Sep 2026
He is right about the premise and wrong about what follows from it. Every visibility figure, from every tool, is produced the same way:
That is a sample statistic, the same shape of thing as a poll. No part of it is magic and no part of it is a guess, but the first step is the one nobody publishes and the one that decides the answer.
A poll is not a guess. A poll with a badly drawn sample is.
Which Makes The Sample The Instrument
So the engine is not the only thing that moved between those two slides. The questions did the measuring, and a set of questions nobody designed will drift on its own, because the answers are probabilistic and the queries were never built to hold still against that.

Repeated sampling is the floor rather than the fix. The spread between two runs of the same question is wide enough that a single pass reports noise, so any number worth putting on a slide is an average over repeats. Repeating a bad question gives a stable bad number.
Which is the trap in most visibility tooling. Repetition is the part that is easy to automate, so it is the part that gets automated, and a dashboard that runs the same flawed set every week produces a beautifully stable line. Stability reads as rigour. It is the one property a broken instrument has in abundance.
We Asked One Category Five Different Ways
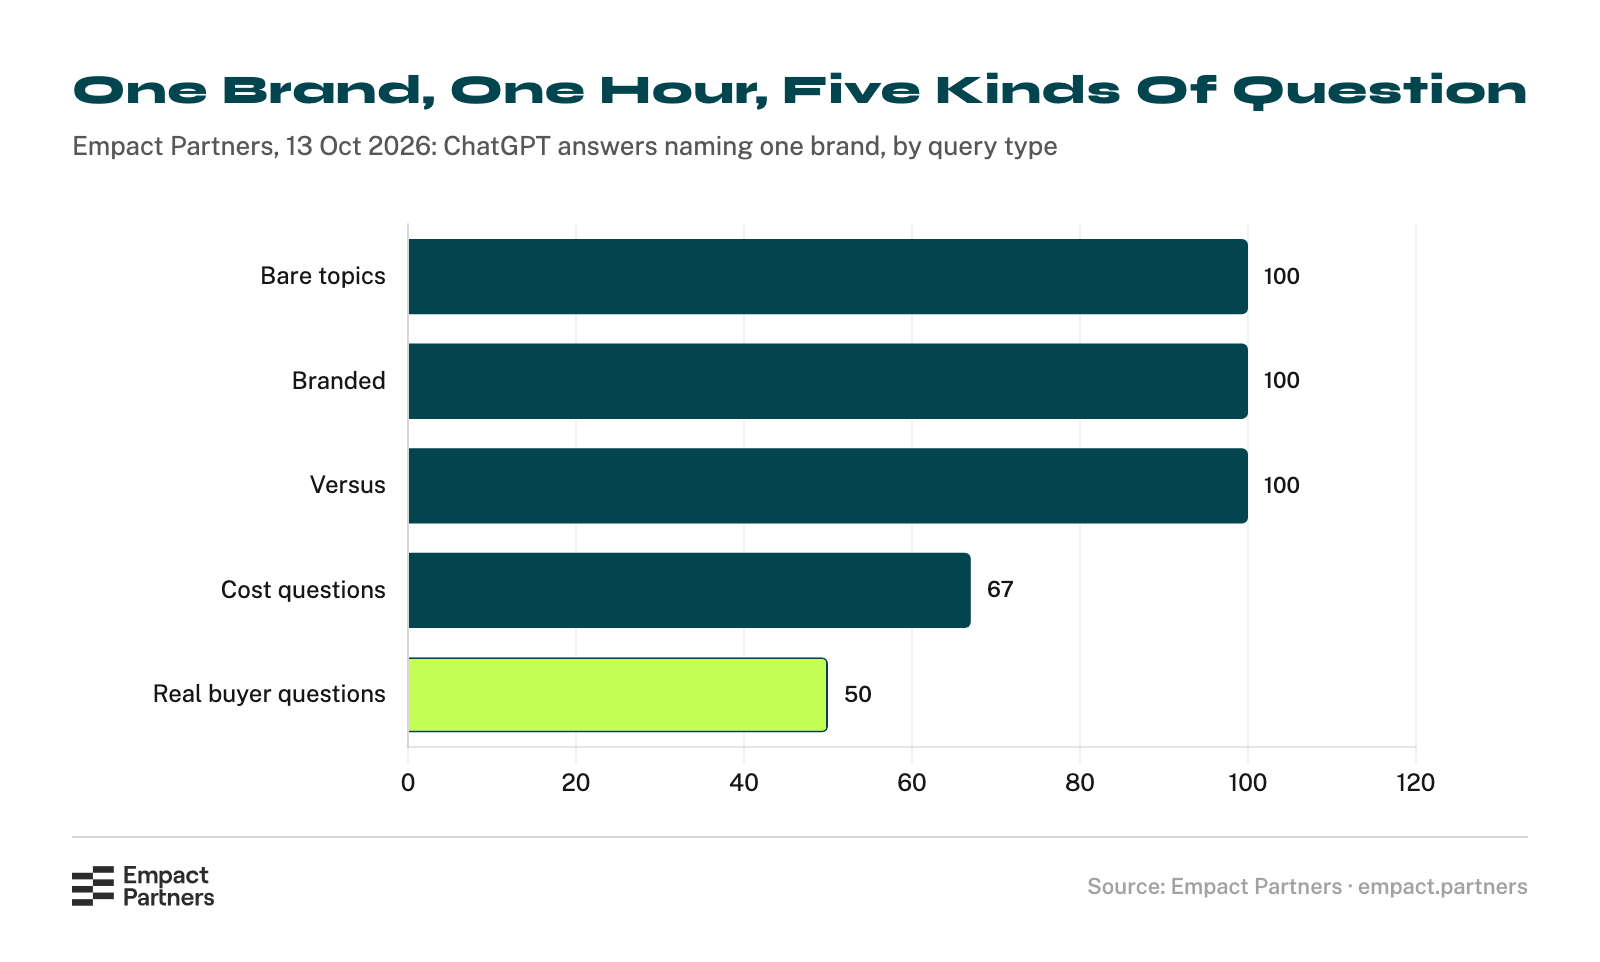
Rather than assert that, we measured it. On 13 October we took one software category, one public brand with no relationship to us, and thirty questions split into five kinds. Same engine, same category, same brand, inside one hour. The only thing that changed between the groups was what the questions were made of.
Three of the five types reported the brand in every single answer:
| What the six questions were made of | Answers naming the brand | Reported visibility |
|---|---|---|
| Bare topics, the category noun on its own | 6 of 6 | 100 |
| Branded, with the brand in the question | 6 of 6 | 100 |
| Versus, the brand against a named rival | 6 of 6 | 100 |
| Cost and budget questions about the category | 4 of 6 | 67 |
| Real buyer questions, a situation in a buyer’s words | 3 of 6 | 50 |
| All thirty pooled | 25 of 30 | 83 |
Fifty against a hundred, for the same brand, on the same afternoon. Pool the lot and you report 83, which is a real number produced by a real count and describes nothing a buyer would recognize.
The limits are ours and worth stating before the conclusion. One engine, one category, one brand, one pass per question, six questions per group, and three groups sat at the six-of-six ceiling, so the gap is demonstrated and its true size is not. It shows composition moves the number. It does not say how far it moves in general, and no budget decision follows from it alone.
Where the brand was missing
The three buyer questions it failed are the interesting half. Two-week sprints. Time tracking with invoicing. A remote software development team. Each names a situation, and in each the engine preferred a tool that fits that situation better.
So the two ends of the set measure different things and report them under one word. A generic question measures how big a brand is. A specific buyer question measures whether it fits. Only the second is the thing anybody is buying.

Run the same count on your own set
It took an afternoon and about two cents of engine time, and the method is not ours to keep:
The fourth step is the one that changes the meeting. A single pooled figure can be defended for a quarter. A pooled figure sitting next to the buyer-question figure cannot, and the gap between them is the brief for the next quarter’s work.
Four Kinds Of Query That Move Your Number On Their Own
Before anything is rebuilt, read your own list. Four kinds of query change what gets measured without anything about your brand changing, and striking them is an afternoon’s work.
Strike those four and the number moves on its own, with nothing changed anywhere else. Our own count puts the gap at fifty points between the cleanest group and the three dirtiest, which is more than enough to explain a swing like Thursday’s without anything happening to the brand at all.
We Graded A Set That Had Already Passed The Script
Here is the part of this we can only know because we run it. Empact Partners builds query sets as the instrument for every visibility study inside Generative Engine Optimization, the workstream that works on whether an engine recommends you at all when a buyer asks it for options.
On one seven-thousand-query set, the deterministic checks had already passed: the duplicates were gone, the banned phrasings were gone, the length and opener distributions were inside their bands. By every automated measure the set was finished.
What the second pass found
Then a reader went through it query by query. Roughly a third of the set was rewritten and under one percent was thrown away. The problem was almost never a query that was obviously wrong. It was a query that measured something a little to the side of what the set was built to measure.
Afterwards we re-ran the same deterministic checks against the corrected set. They rejected nothing, exactly as they had rejected nothing before the corrections. The script passed both versions, which is the clearest statement available of what a script is able to see. On our reckoning it catches about one percent of what is wrong with a query set.
The Answer Is One To Three Thousand, And That Is The Smaller Half
The number people want is real, so here it is. A brand visibility study we would stand behind runs between one and three thousand queries, spread across the full surface of use cases rather than deepened on a few.
The reason is unglamorous. Concentration falls as specificity rises, so a set weighted toward broad questions and a set weighted toward narrow ones will report different visibility for the same brand in the same week, both correctly.
What that means in practice is that two honest studies of the same brand disagree by design:
| A set weighted broad | A set weighted narrow | |
|---|---|---|
| What its questions look like | Category-level, few constraints | Situations, roles, sizes, budgets |
| Who tends to win its answers | The largest, best-known names | Whoever fits the stated constraint |
| What a high number means | The brand is well known | The brand fits the cases asked about |
| What it misses | Every buyer with a constraint | The buyer with no constraint yet |
Neither column is the wrong way to build a set. Reporting a number from one and comparing it with a number from the other is the error, and it happens most often inside a single company across two quarters.
Which is also why a short set gets repaired the wrong way. The instinct is to top it up with whatever queries are easiest to add, and that quietly changes what the study is about. A refill belongs against the specific use cases that came up short, never across the set.
The Twin Almost Nobody Builds
One more thing decides what a set can see, and it comes from Qvery, our sister company, which measures what the engines answer and what they cite. In August it ran paired versions of the same buying questions, once bare and once with a single real constraint attached.
| Bare question | One constraint added | |
|---|---|---|
| How it reads | best ecommerce platform | best ecommerce platform for a store doing under $10k a month |
| What answered it | Review and roundup publishers | The vendors’ own documentation |
| Shared with the other’s top ten | Three sources | Three sources |
| Its most-present source appeared in | 12% of its answers | 10% of its answers |
The rates barely moved. Across the twenty most-present sources the median gap between the two phrasings was under three points, and not one moved ten points or more.
The roster moved almost entirely. Each phrasing’s top ten shared only three sources with the other, which means a set built from bare head terms never sees the vendor layer that answers constrained questions at all.
Qvery is ours, so treat the finding as an interested party’s and ask us for the runs behind it. Qvery states its own limit plainly, and it holds. The pattern tells you how to design a set. It does not prove that redesigning one moves anybody’s visibility.
What We Would Do Before Thursday
Not a rebuild. Read the existing list, strike the four kinds above, and count what is left. Then put the instrument on the slide underneath the number:
Five lines under a number is not a hedge. It is the difference between a measurement and an assertion, and it is what lets the same slide be compared with itself next quarter.
The two numbers probably came from sets that were not the same shape, and saying so upstairs is a stronger position than defending either figure.
The half that is not an afternoon
Then the longer half, honestly. Building a set worth trusting means mapping the use cases before the phrasings, weighting them by how central each one is, generating at the scale above, and having somebody read every line of it. The reading is the part that cannot be bought, and it is the part our own numbers say the scripts will not do for you.
So the quit point is worth naming before anybody commissions a study. If nobody will read the set line by line, do not buy the three thousand queries. Build two hundred that are all real buyer questions, report that number and its composition, and say plainly what it does not cover. A small honest instrument beats a large uncalibrated one, and it costs less to maintain.
We have written on measuring AI search visibility once the instrument is settled, and on the two numbers a board usually conflates.
Most teams stop at the dashboard they do not trust, because the dashboard arrives and the set does not. If your own visibility number moved and you cannot tell anybody why, book time with me and we can work out whether the instrument is the problem.


