
How to Test Your Website the Way a Buyer’s AI Agent Would
Send one AI agent to find your price, compare your plans and reach your booking page, then turn its action log into fixes with owners.
On this page
Empact Newsletter
One email a month on what is working in AI search and SaaS go-to-market.
When a buyer asks an AI agent to find your price, compare your plans and book a demo, the agent starts on the page an AI answer cited. Your analytics may log the visit but not the menu that stopped it. A teammate clicking through misses it too, because they know where everything is. This test finds those stalls with one agent and three buyer tasks. Then each stall gets someone to fix it and a second run to prove the fix.
Empact Partners works on both ends of that route for SaaS companies. We work to get the product named in ChatGPT, Claude and Google AI Mode answers, and on the pages a buyer crosses from there to a price or a signup.
The runs reported below were on our own site, where we tested first.
The test runs from a terminal on your own computer and needs four things:
This test leaves out your support desk, a logged-in product and crawler access, which is a separate test with its own fixes.
Which Page the Test Starts On
An agent sent by an AI answer lands on the page that answer cited, reads it, and has to find the price, the plans and the booking from there. That page is often one nobody built as a way in.
Step 1: Find the pages AI answers cite for your buyer questions
Ask the questions your sales team hears on first calls in ChatGPT and Google AI Mode, and in Claude. Open the sources under each answer and copy every URL on your own domain into a sheet, one row each, with its question beside it. The page that turns up most is where your test starts.
How rarely that page is one built to sell shows in one partner’s record from the Empact Panel, a tool we built that asks those three engines a partner’s buyer questions each week and records every page their answers cite. This card covers the 30 days to 15 November 2026, with the cited pages split by section:
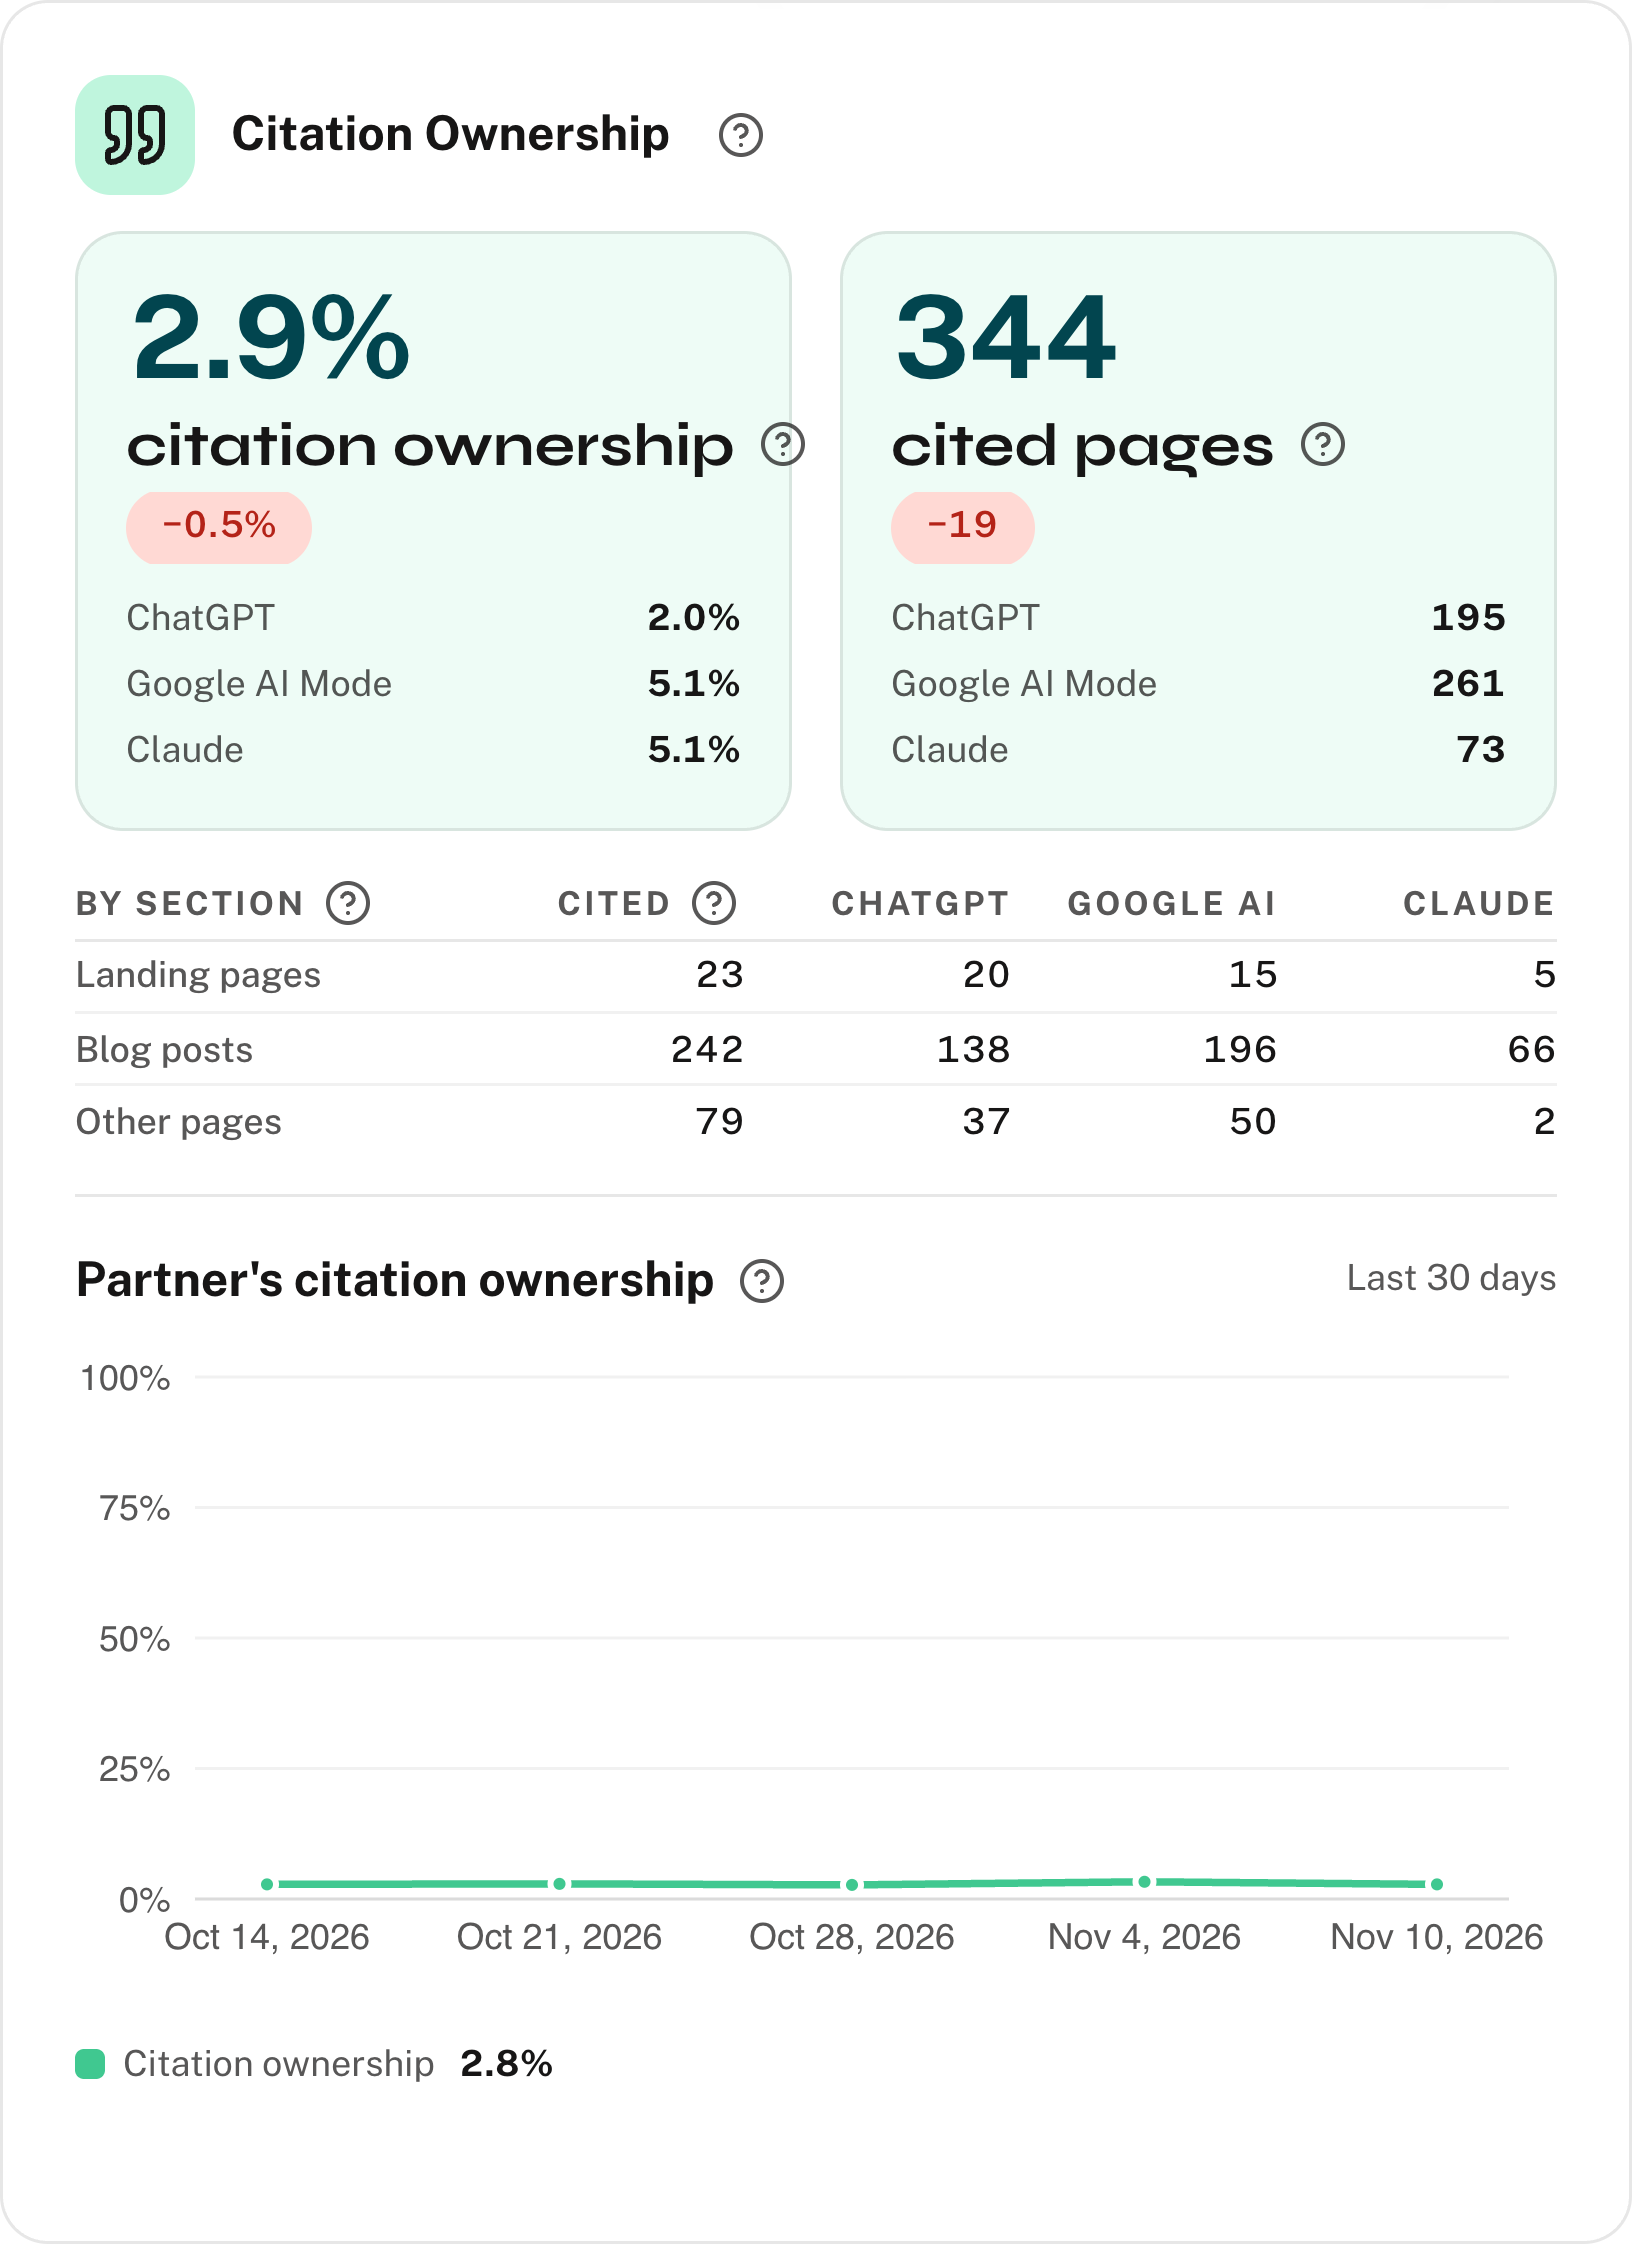
The engines cited 344 different pages of that partner’s site, and only 23 were landing pages, the pages a team usually tunes for buyers 4. Blog posts made up 242 of them. The card counts pages, not visits, but most of the doors those answers open are articles, not pages built to sell.
Ours started on one of our case studies, which linked to our booking page and to nothing an agent could see that said what we sell. If none of your pages turns up in the answers, start at your homepage, and treat the absence as a visibility problem to fix before a usability one.
Before you set anything up, you can get a first look at the route from your homepage. The free check below follows every click from there to your signup form, up to three deep. It notes each field and promise on the way, emails you five fixes or checks and never submits the form. It is a single walk of a route that the full agent walks again for our partners whenever their site changes, so a step a release adds gets caught.
Setting Up the Agent and Its Three Tasks
The agent is Claude Code, driving a real Chrome through Microsoft’s Playwright MCP server, a small Model Context Protocol (MCP) program 1. It hands the AI model a browser and reads each page to it as buttons, links and text. The agent’s record of every action, which you open in step 6, matters more than its summary.
Step 2: Save the browser config and start it once
Before the first run
Make an empty folder.
Everything the test writes lands in it.
Save the browser config.
Copy the file below into the folder as
playwright.json.Start the server once by hand.
Run the warm-up command there, so the package is cached before any agent needs it.
The config we ran on 28 October, pinned to that day’s version:
{
  "mcpServers": {
    "playwright": {
      "command": "npx",
      "args": [
        "@playwright/mcp@0.0.83",
        "--headless",
        "--isolated",
        "--save-session",
        "--output-dir",
        "playwright-output"
      ]
    }
  }
}
Headless means no window opens. Isolated keeps each browser profile in memory, so every task starts with no cookies or history, and the last two lines log every action into playwright-output 1. A newer version should take the same flags, but we ran only this one, so pin whichever version you use.
npx @playwright/mcp@0.0.83 --versionIt should print Version 0.0.83. Pinned and cached, the server started in under three seconds on our machine. Unpinned, npx checks the registry on every start, which on our machine was slow enough for the agent to begin before its browser was ready.
Step 3: Write the three tasks
Each task is one prompt, and the three differ only in the paragraph that starts “Your task”. This is task A as we ran it, with our entry page and topic swapped for the two placeholders you fill in:
You are a buyer's research agent, and the browser is your only tool. An AI assistant cited this page when I asked it for help with <what your buyer asked about>:
<the page your sheet puts first>

Your task: find out what it costs to work with this company and how they set their price. If the site does not say, tell me that, and tell me what the site wants a buyer to do to get a price.

Rules:
- Start at that page. Stay on this company's own website and the pages it links to. Do not use a search engine.
- Do not submit any form, book any time, or type any personal details.
- If a cookie banner or popup appears, close it.

When you have finished, or cannot get any further, end your answer with this report, filled in:

RESULT: done / partly / stuck
ANSWER: what you found, in one or two sentences
PAGES: every URL you visited, in order
STOPPED AT: the page and the element where you stopped, and why
WOULD HAVE HELPED: what on the site would have let you finish faster, or at all
Task B swaps in the first paragraph below and task C the second. Rewrite task B’s first two sentences the way your own buyer describes their situation.
Your task: I run a product-led SaaS company. Signups arrive but stall, and I want my product recommended when buyers ask ChatGPT about our category. Find what this company offers, tell me which of its offerings fit my situation, and how they differ from each other.

Your task: start a request to talk to this company about working together. Go as far as the step where I would type my own name or email, then stop. Do not submit anything. Tell me each step it took to get there, and what the final step asks me for.
The search ban keeps every stall on your own site, and the no-submit rule keeps test bookings off your calendar. Before any run, write down what done means for each task, so the agent’s report can’t set its own bar. We sell services rather than plans, so our task B asked which services fit. These were our lines 3:
Scroll horizontally to see all columns when the table is wider than this page.
| Task | Done, as written before the run | Counts against it |
|---|---|---|
| A: find the price | Says whether a price is published, what the site says about how one is set, even if that is nothing, and how a buyer gets one | An invented figure |
| B: compare the plans | Reaches two or more service pages and says, from them, which fit and how they differ | An answer from the starting page alone |
| C: start a demo request | Reaches the name or email step, names each step, types nothing | Typing or submitting anything |
Step 4: Run each task in its own session
Save the three prompts as task-a.txt, task-b.txt and task-c.txt in the test folder and run task A from it. When its answer ends in the filled report, run the same command with task-b.txt, then task-c.txt, each a new session that remembers nothing of the last:
claude -p --model claude-sonnet-5-5 --effort medium \
  --setting-sources project \
  --strict-mcp-config --mcp-config playwright.json \
  --tools "" --allowedTools mcp__playwright \
  < task-a.txt
The flags limit what the agent can see and do 2:
--tools ""removes every built-in tool, so the agent reads your pages only through the browser.--strict-mcp-configwith--mcp-configloads the Playwright server and nothing else.--allowedToolslets the browser tools run without stopping to ask.--setting-sources projectloads settings only from the empty test folder, so your own settings and instruction files stay out.
Checking the Agent’s Report Against Its Action Log
The report at the end of each answer is the agent’s account of its own run, grading the site and itself at once. You decide the verdict by reading the action log against your completion line.
Step 5: Copy each report into the log
Put the report lines into your sheet, one row per task, and add the column the agent doesn’t fill: your verdict against the completion line you wrote first 3.
Scroll horizontally to see all columns when the table is wider than this page.
| Task | Agent’s result | Our verdict | What the agent said would have helped |
|---|---|---|---|
| A: find the price | partly | done | “A short note on whether they charge a retainer, a project fee or performance-based fees would also have answered it.” |
| B: compare the plans | partly | done | “A Workstreams dropdown that works as plain links.” |
| C: start a demo request | done | done | “A contact page or a ‘Contact us’ link in the site navigation, plus a plain contact form, would have avoided booking a call just to get in touch.” |
In task B the agent read two of our eight service pages, said which fitted a product-led buyer and how they differed, and marked itself partly for skipping the other six. Our completion line asked for a fit and a difference, so the run counts.
What it couldn’t answer, which service comes first, went into the sheet as a fault in our pages. In task A it reported correctly that we publish no price and say nothing about how one is set. It marked itself down for that gap too.
Two of our three runs finished their task and still reported it as partly done, because the agent was marking the site down for what it lacked.
Step 6: Check each claim against the session log
Open playwright-output, then the folder named session- and a number, then session.md. Each action sits under a heading that starts “Tool call”. Check that every page the report names was opened, and that the log ends where the report says the agent stopped. Then trace how the agent got from the entry page to its answer.
That last check found our worst stall. On the case study the agent noted “Workstreams is a menu button.” On our Partners page it clicked that button and found nothing: “The dropdown didn’t expose links. I’ll try the homepage.”
There it ran a script over the page code to pull out every link, and only then found the pages that say what we sell. The first service page was the fourth page it opened, and the report mentions the script only in passing, under what would have helped.
Is Each Stall a Site Fault, a Choice or a Test Failure?
A stall is one of three things: a fault in the site, a choice the company made on purpose, or a failure of the test itself. Only one of them should change the site:
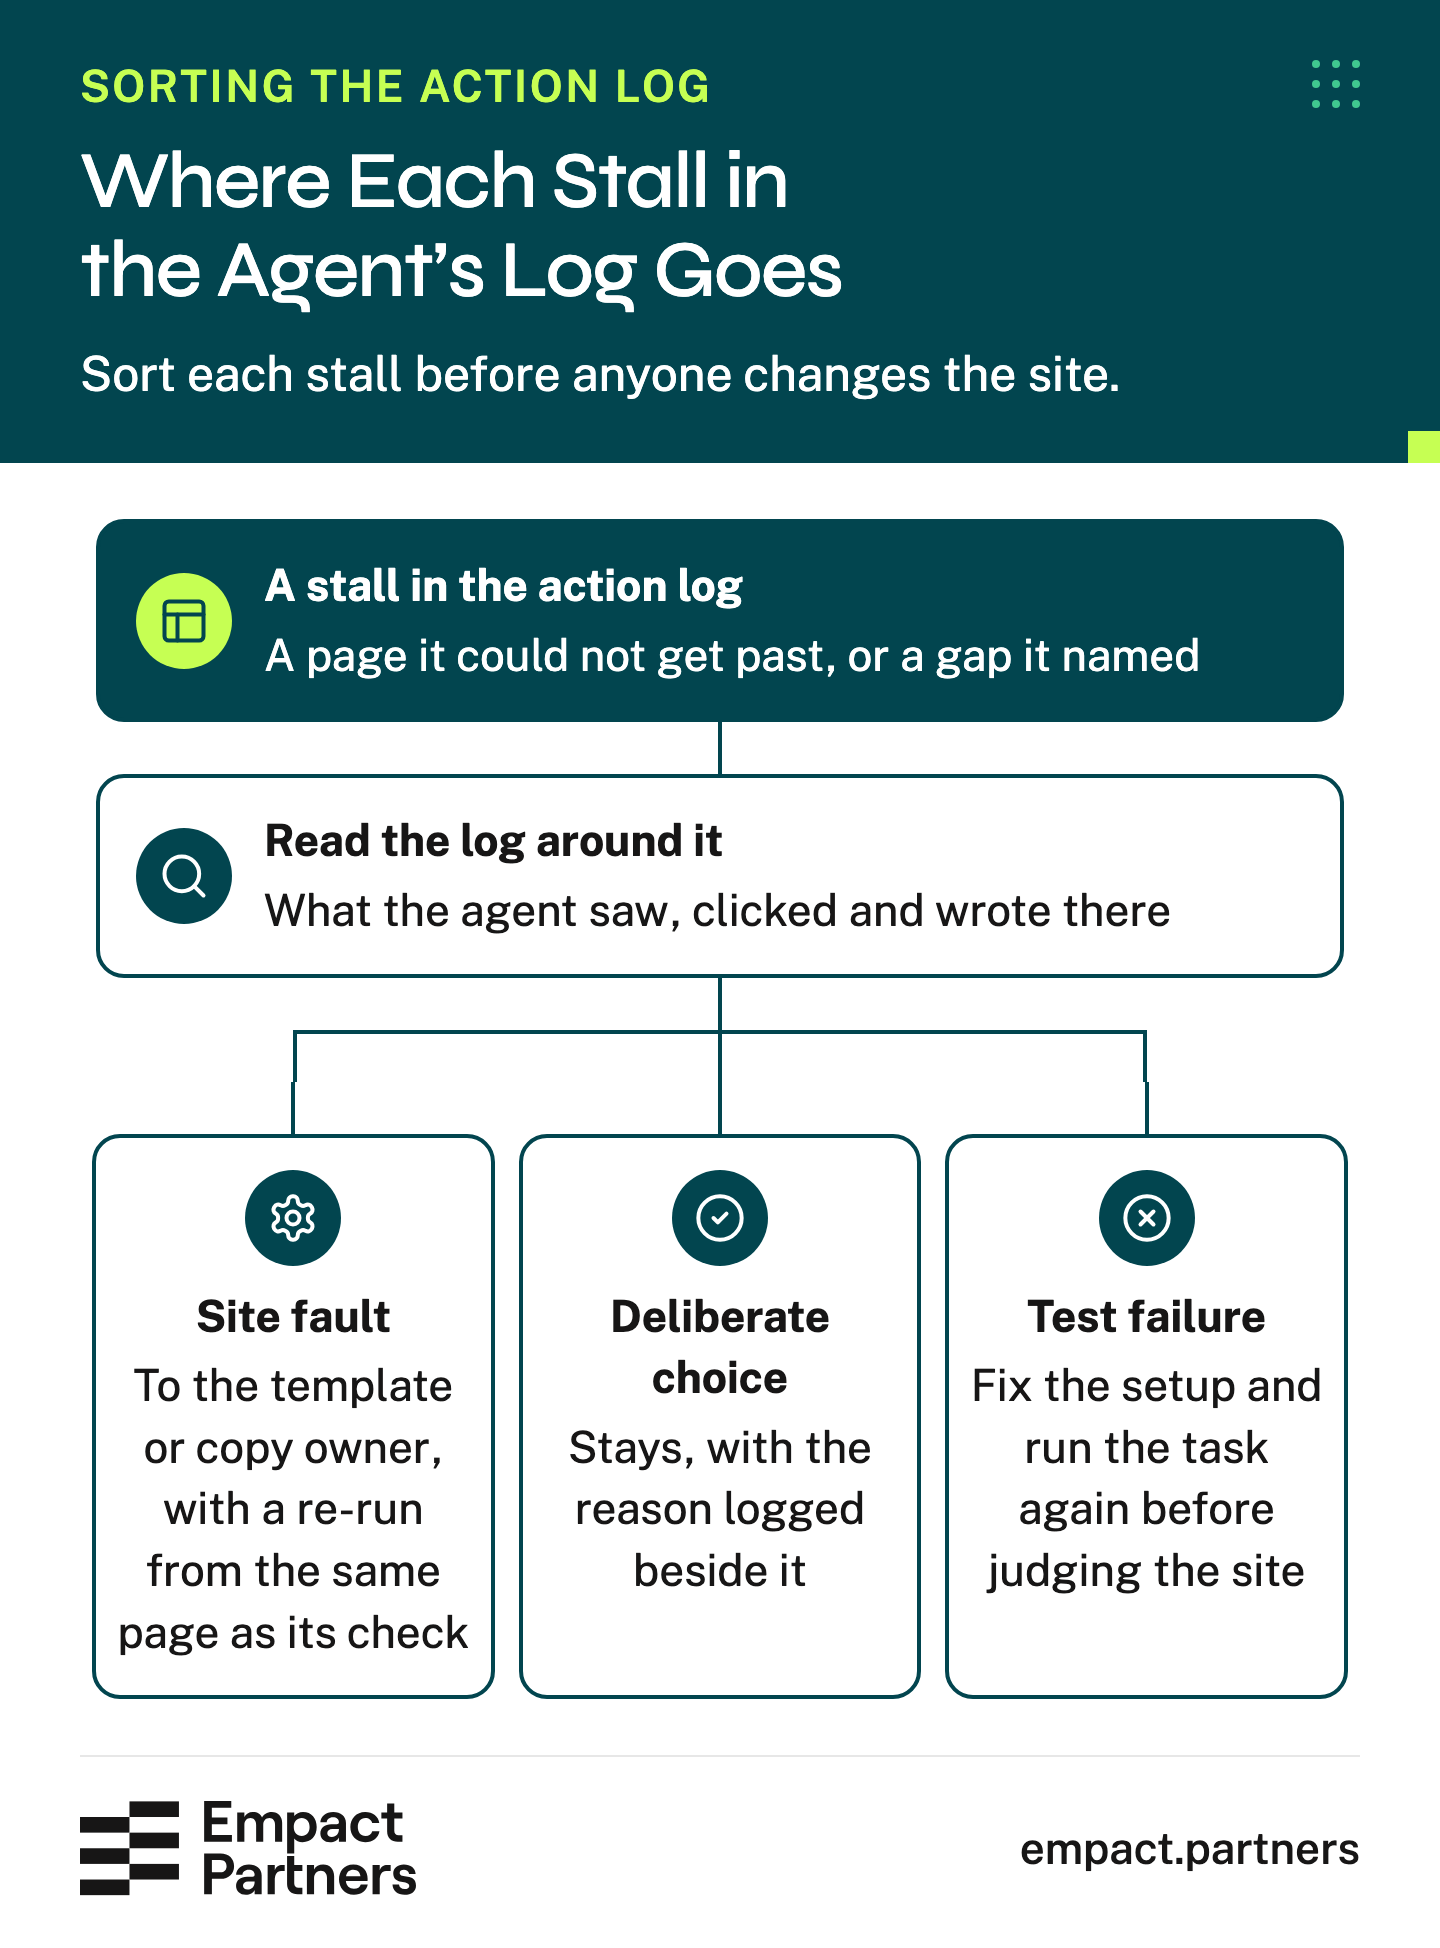
Sort every row before anyone fixes anything, or somebody undoes a decision made on purpose.
Step 7: Give each stall a cause and an owner
Add columns for the cause, the fix and who makes it, one row per stall the logs show. Our five site faults 3:
Scroll horizontally to see all columns when the table is wider than this page.
| Stall | Cause | Fix | Owner |
|---|---|---|---|
| The Workstreams menu shows a button and no links | Its links never reach the agent, even after a click | A menu that opens on a click with readable links, and the service pages shown again as plain links | Site template owner |
| No page says how a partnership is priced | No sentence says how an engagement is scoped and charged | One plain sentence on how pricing works, with no figure | Whoever decides what the site says about price |
| A sidebar block on every article points to a “Coming Soon” page | The template promotes an eBook that was never put live | Remove the block, or put the eBook live | Site template owner |
| The Product-Led Growth page hides its answers in a closed accordion | Collapsed answers stay hidden until the agent reads the page code | Show the main answers in the page copy | Site template owner |
| The Generative Engine Optimization (GEO) and Product-Led Growth (PLG) pages overlap | Neither says who it is for: “no clear way to tell whether GEO or PLG should come first” | A line on each page naming who it is for, so a buyer can tell which comes first | Content team |
The menu was the first fix on our sheet. It sat in the header of every page on our old site. On the pages the agent tried, it was the only route to the service pages. The site you are reading has replaced that one. Its Workstreams menu opens on a click to plain links and the “Coming Soon” page is gone, so those two rows close when the same re-run passes against it.
The menu went first because it decided what an agent could learn from every page, wherever an answer dropped it. Our own clicking around never caught it, because each of us goes straight to the pages we know are there.
 Vlad Shvets on LinkedInOpens in a new tab
The rest of what the agent flagged stays, and the log says why:
- No published price. We never publish a fee. The fix above adds how pricing works, never the number.
- One way in. The agent wanted a contact form. Booking a call is the route we chose, one click from its starting page.
- The starting page. It noted the case study was not about SaaS signups. Which page an answer cites is visibility work, outside this test.
- The first click. In task C the booking link took longer than the browser server’s five-second default wait, so the agent opened its address directly. One run is one observation, so it is a row to watch.
- No browser. Test noise, covered in step 2.
How to Know a Fix Worked
Step 8: Write the re-run beside every fix
For each fault, write the check that proves it before anyone starts the fix. The check is the same prompt from the same entry page in a fresh session, read against what you expect. A fix is finished when the re-run meets that check, not when the agent gets a little further. Ours:
The re-run passes when
- The menu: in task B, the pages visited include a service page within two steps of the entry page, with no script
- The price sentence: in task A, the report’s answer says how pricing works, with no figure in it
- The sidebar block: in task A, the “Coming Soon” page no longer appears among the pages visited
- The accordion: in task B, the agent quotes the answers without reading the page code
- The overlap: in task B, the answer says which service comes first for the buyer
- The watch row: in task C, the booking link opens on the first click
Run each check twice before you close its row, since one passing run is one observation. Our test changed nothing on the site and submitted nothing. Changes to the menus, the templates and what a page says about price are for a person to make.
Every one of those checks is only as good as the page the test started from.
Our first run on your site would start where the Panel shows the engines sending your buyers. That page is rarely the one your team would test. From there we run the three tasks, read each log against its completion line and sort every stall. You get back a sheet where every fault has its fix, its owner and the check that proves it:
What a buyer-agent test with us covers
- Entry pages from the Panel’s weekly record, wherever Claude, Google AI Mode or ChatGPT sends your buyers
- A completion line for each buyer task, written before the agent runs
- One fresh browser per task, with nothing typed into a form
- Every stall checked against the action log and sorted as a fault, a choice or test noise
- A re-run from the same page for every fix, so a row closes on evidence
If your team would rather fix its own pages, the free playbook below covers the engines’ side of the same route, so the pages a buyer needs stay reachable for ChatGPT and Google AI Mode whenever you ship a change.
Testing With an Agent That Reads Screenshots
The run above was one agent on one day. Claude Code with Playwright reads each page as its buttons, links and text, so a menu that opens when a visitor hovers over it showed the agent nothing. It got past that by running scripts over the page code, which is also how it pulled answers out of the closed accordion.
An agent that works from screenshots, such as Claude in Chrome or ChatGPT’s agent, sees the page as a person does and may fail the other way round. If you use one, paste in the same three prompts and keep the same log.
Whichever kind of agent you test with, one number tells you whether the fixes are working. Watch it on every re-run: how many pages stand between the page an answer cites and the first page that says what you sell. On the old site the first service page was the fourth page the agent opened, and only a script got it there.
Frequently Asked Questions
Do we need an engineer to run this test?
Not for the run itself. Someone comfortable opening a terminal can install Node.js, save the config file and paste the commands. A marketer can write the three tasks and the completion lines, and should, because they know what a buyer asks on a first call. You will need an engineer for the fixes: navigation menus, page templates and anything that changes how a page is built belong to whoever owns the site’s code.
Which page should the agent start from?
The page answers cite most for your buyer questions, since that is where an agent following an answer lands. When the engines disagree, start from each engine’s most-cited page, because buyers on Claude, ChatGPT and Google AI Mode can land on different doors. Test a most-cited page even if you would never have picked it. If none of your pages is cited, start from the homepage and treat the missing citations as the bigger problem.
Will the agent book a meeting or send one of our forms?
The prompt forbids typing personal details, submitting a form or booking a time. In our run it held: the agent picked a slot on the booking page, which holds it in the page only, reached the details form and stopped. Don’t take that on trust. After every run, open the action log and check that the only actions are opening pages, clicking, reading and waiting, with nothing typed into a field.
Does it matter which AI agent we test with?
Yes, because agents read pages differently. One that works from the page’s structure, as ours did, can read hidden text and still miss a menu that opens on hover. One that works from screenshots sees what a visitor sees and can miss text a visitor would have to click to reveal. Your buyers will use both kinds, so run the same three prompts in each and keep both runs in one log, with a column naming the agent behind each row.
Should we test more than three buyer tasks?
Start with the price, the plan comparison and the demo request, since a buyer’s shortlist depends on those three. Add a fourth only when buyers raise it on first calls, such as finding a security page or checking an integration. Give every task its own fresh session and its own completion line, because an agent that remembers the last task finds pages faster than a buyer’s agent would. Add only as many tasks as you can read in full.
Do we have to publish prices for the agent to finish the price task?
No. A company that sells through a conversation can pass the price task by saying plainly how pricing works and how a buyer gets a quote. In our run the agent marked itself partly. We counted the task as done against our completion line, because it reported the missing price correctly and named the route. Its only complaint was that no page explained how pricing is set. One sentence on what drives the price, with no figure in it, answers that.
What counts as proof that a navigation fix worked?
A check written before the change and met afterwards, by an agent that has never seen the site. Keep the old action log beside the new one, so whoever approves the change sees the route shorten instead of trusting the summary. Expect a different path on the re-run, since pages and wording changed, and accept it if it meets the check. If it passes by a route nobody planned, such as a search box, note it, because a buyer’s agent may not find that route.
How often should we run the three tasks again?
After any change to your navigation or page templates, after a redesign, and whenever the pages AI answers cite for your buyer questions change. A cited page that moves is a new front door that nobody has tested yet. If you record your cited pages every week, the entry pages for the next round are already known. Between those events, a run each quarter catches drift that nobody announced.
Is this the same as checking whether AI crawlers can read our site?
No. A crawler test asks whether an engine can fetch and read your pages at all, and your server logs and the raw page text answer it. This test assumes the page loads and asks whether a buyer’s task can be finished from it. A site can pass one and fail the other: our old pages read fine, and the agent still needed a workaround to reach a service page. If your logs show the engines’ crawlers being turned away, fix that first.
Can an agent fix the faults it finds?
Keep navigation, templates and anything about price with people, since each one changes what every visitor sees. An agent with access to your publishing system should make only small edits that are easy to undo, such as a page description or an image’s alt text. A person reads each one before it ships. This test changes nothing on purpose, so each fix goes to the owner named on its row.
Sources (4)
- Microsoft, "Playwright MCP" (2026)↩1↩2project README, 2026.
- Anthropic, "CLI reference" (2026)↩1Claude Code documentation, 2026.
- Empact Partners, "Own-site browser-agent run, 28 October 2026" (2026)Empact Partners' own data↩1↩2↩3↩4the three task prompts, the completion lines written before the run, the six session transcripts and the sheet of fixes, read on 13 November 2026.
- Empact Panel, "one partner’s Citation Ownership card, ChatGPT, Google AI Mode and Claude, 30 days to 15 November 2026" (2026)Empact Partners' own data↩1read on 15 November 2026.
Keep reading
GEO How Fast AI Engines Notice New Mentions and Why Some Fixes Lag
ChatGPT can cite a new page within a week and still use a company's old name for months. Here is how to tell which clock an answer runs on.
GEO How to Choose a GEO Consultancy Whose Numbers You Can Check
One week of AI answers can show a brand flat, up 17 points or down 52. Four requests test whether a GEO proposal can prove its results.
GEO Does Google's AI Search Guide Justify Cutting Off-Site Work?
Use the pages AI Mode cites to decide where your SaaS team should focus website fixes, outreach and community work.